AI benchmark / Game-based evaluation

System 2 Arena

An AI strategy benchmark that pits frontier language models against each other in turn-based games and records decision logs and raw replays.

Clear22/30
Useful25/30
Specific18/20
Complete15/20
System 2 Arena screenshot

Why it was accepted

The page clearly presents a real AI benchmarking product with a defined purpose: comparing large language models in strategic games and ranking them with Glicko-2. It includes enough visible detail for a useful listing, including supported games, head-to-head match format, replay evidence, and match-cost context.
Weakness

The snapshot shows a showcase/admin launch form, but not the broader benchmark catalog, published leaderboard examples, or documentation on how results are generated and validated. It also does not show whether visitors can run their own matches or only view completed exhibitions.

Review status

90 days ago #1898 ↓ -1

Last evaluated 90 days ago. Current rank #1898. Down 1 spot in the rankings.

Score history

80

Related listings

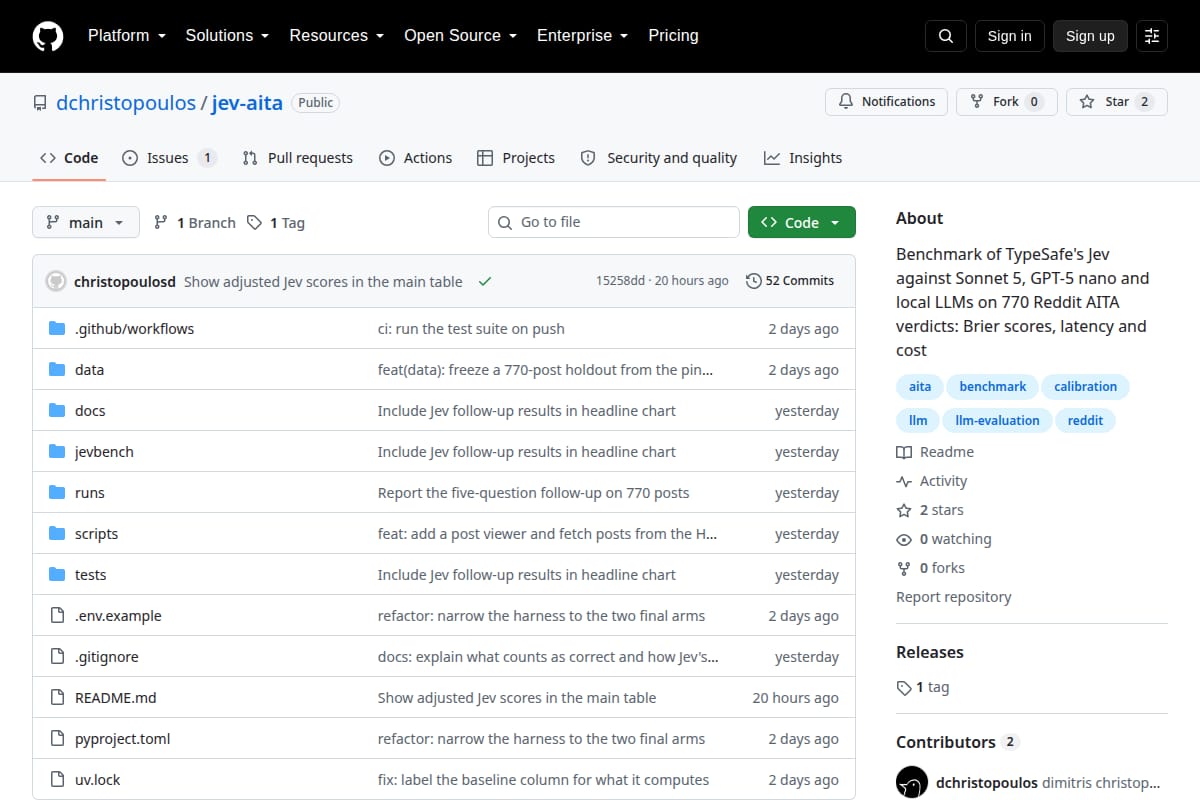
Jev vs. LLMs on 770 AITA posts screenshot

AI benchmark / LLM Evaluation

A GitHub repo benchmarking TypeSafe’s Jev against Sonnet, GPT-5 nano, and local models on 770 Reddit AITA verdicts, with Brier scores, latency, and cost comparisons.