
AgentDish directory
benchmarking
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#25
↓ -3
SigMap
SigMap is a deterministic grounding layer for AI code work. It generates a signature-and-evidence map, helps pick relevant files, validates coverage, and judges whether an AI answer is grounded in the repo. |
Developer Tools / AI Code Assistance | 91 | ↓ -3 | 102 days ago | Details |
#62
↓ -2
BoundaryBench
BoundaryBench is an open-source benchmark for coding agents running under hardened sandbox policies. It compares harnesses like Claude Code, Codex, Terminus 2, and Grok on Terminal-Bench tasks and includes quickstart, policy controls, and result export tools. |
Developer Tools / Code Assistant | 90 | ↓ -2 | 70 days ago | Details |
#104
↓ -3
trycua/cua
Open-source infrastructure for computer-use agents, with sandboxes, SDKs, benchmarks, and desktop automation tooling for macOS, Linux, Windows, and Android. The repo also includes Cua Driver, CuaBot, Cua-Bench, and Lume for VM management. |
Developer Tools / AI Agent Infrastructure | 90 | ↓ -3 | 163 days ago | Details |
#120
→ 0
MicroLLM Lab
A browser-based lab for running, comparing, and benchmarking small language models on-device with WebGPU. |
Developer Tools / Code Assistant | 89 | → 0 | 16 days ago | Details |
#122
→ 0
AgentLearn
Free curriculum for learning AI agents, LLM evaluation, and benchmarking, with 42 lessons, interactive labs, runnable JavaScript, and saved progress. |
Education / AI Learning | 89 | → 0 | 21 days ago | Details |
#230
↓ -3
BlueVetaUpright — Research & Methodology
Technical research page for BlueVetaUpright, a product-photo orientation correction system. The page explains the problem, the system design, dataset methodology, and benchmark results, including comparisons against ChatGPT, Gemini, and Claude. |
AI Product / Research / Computer Vision | 88 | ↓ -3 | 19 days ago | Details |
#272
↓ -3
AI Hardware Fit — 내 GPU에서 돌아가는 AI 모델 찾기
오픈소스 AI 인프라 산정 도구로, 보유 GPU나 목표 워크로드를 입력해 실행 가능한 모델, 필요 장비, 배치안, TCO 비교까지 계산합니다. LLM, RAG, VLM, 아바타, 음성 워크로드를 다루며 한국어/영어 UI와 여러 추천 경로를 제공합니다. |
Developer Tools / Code Assistant | 88 | ↓ -3 | 52 days ago | Details |
#288
↓ -3
Is AI Dumber Today?
A community-tracked index of how users feel AI model quality is changing, updated hourly from public feedback and direct submissions. |
AI Analytics / Model Tracking / Benchmarking | 88 | ↓ -3 | 62 days ago | Details |
#395
↓ -3
LLMRequirements.com
An interactive guide for choosing local AI hardware and matching open-weights LLMs to specific builds. It offers budget-based build recommendations, a hardware picker, model-to-hardware compatibility, and a state-of-the-local-AI snapshot. |
Developer Tools / AI / ML Infrastructure | 88 | ↓ -3 | 144 days ago | Details |
#410
↓ -3
agent-skills-eval
A TypeScript CLI and SDK for testing whether Agent Skills improve model outputs by running with-skill vs baseline evaluations and generating reports. |
Developer Tools / AI Evaluation | 88 | ↓ -3 | 161 days ago | Details |
#444
↓ -4
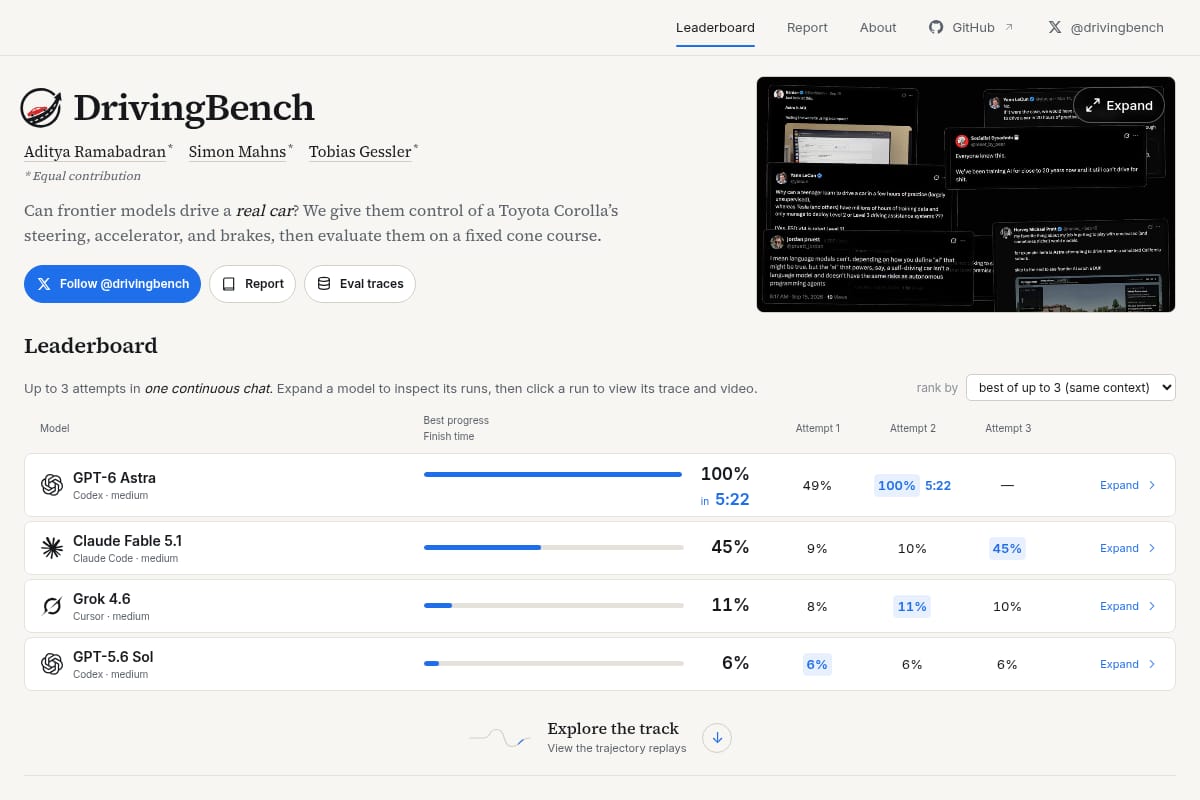
DrivingBench
DrivingBench is a benchmark that tests frontier LLMs on real-world driving tasks in a Toyota Corolla with a cone course, leaderboard, run traces, and replay videos. |
Developer Tools / Benchmarking | 87 | ↓ -4 | 23 days ago | Details |

#462
↓ -4
Ante
Ante is a self-contained coding agent for the terminal with local model support, multi-agent orchestration, and programmatic server modes. The docs highlight offline operation, low resource use, public benchmarks, and integrations for providers, MCP, Slack/Discord, and custom engines. |
Developer Tools / Code Assistant | 87 | ↓ -4 | 38 days ago | Details |
#558
↓ -4
SQLite-Columnar
A loadable SQLite extension that adds column-oriented storage and analytics for fast local OLAP-style queries, with benchmark data and build instructions. |
Developer Tools / Databases & Storage | 87 | ↓ -4 | 155 days ago | Details |
A research article from Applied Compute on how agentic, tool-using workloads differ from traditional LLM benchmarks, with production observations, workload profiles, and an open-source harness for replaying traces. |
Research / Knowledge Work | 87 | ↓ -153 | 163 days ago | Details |
#598
↑ +2
Oko
Open-source code search for coding agents, built on Jev, with benchmarked speed and token-use gains across Codex, OpenCode, and Claude Code. |
Developer Tools / Code Search | 86 | ↑ +2 | 24 days ago | Details |
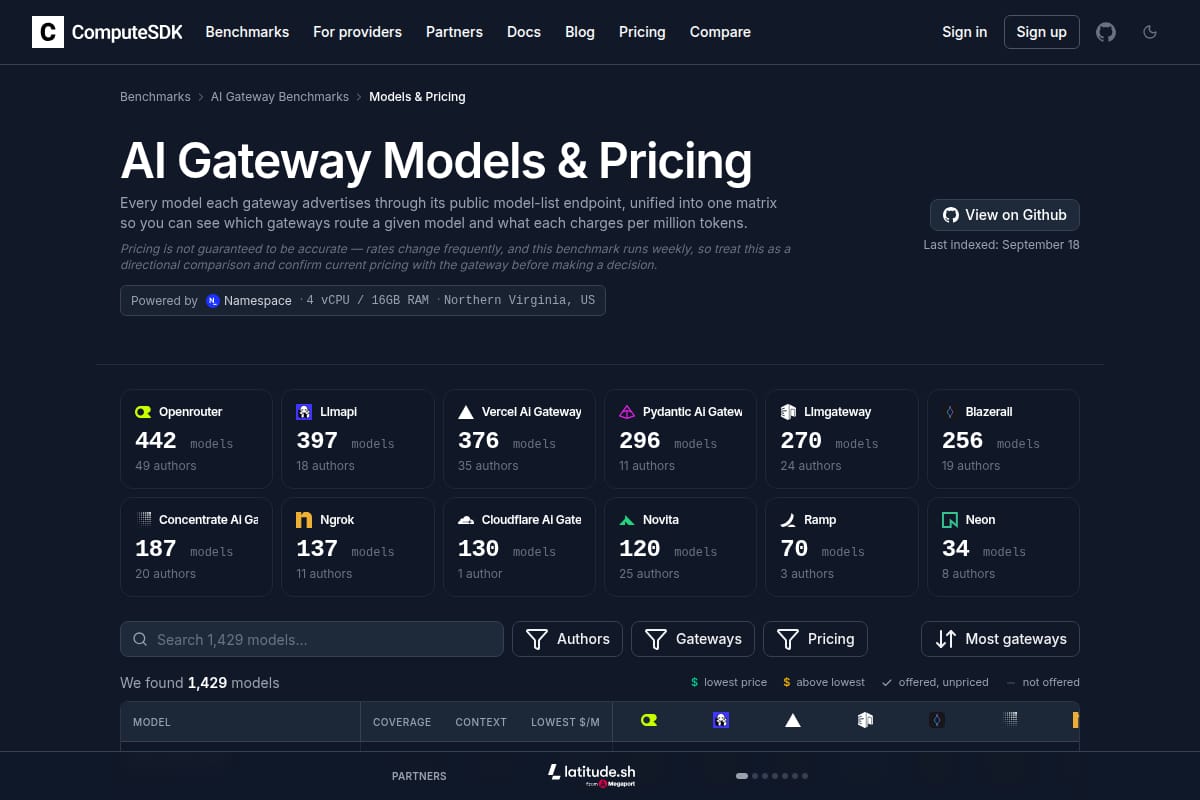
#600
↑ +2
AI Gateway Models & Pricing
A benchmark page that aggregates public model lists from AI gateways into one matrix, showing which gateways offer each model and their per-million-token pricing. |
Developer Tools / Benchmarking | 86 | ↑ +2 | 26 days ago | Details |

#620
↑ +2
Anypick
Anypick is an open library for selecting the best LLM across providers using filters for capabilities, pricing, and benchmarks. It includes Python and TypeScript implementations, provider support for OpenRouter and Vercel AI Gateway, and examples showing how to pick a model by constraints and strategy. |
Developer Tools / AI Model Selection | 86 | ↑ +2 | 37 days ago | Details |
A research repo for reducing hallucinations in LLM-generated code using semantic triangulation, with setup, benchmarking, experimentation, and reproducibility instructions. |
Developer Tool / Code Quality | 86 | ↑ +2 | 67 days ago | Details |
#725
↑ +2
Atelier
Open-source runtime for coding agents that sits underneath Claude Code to reduce tool calls, shorten context, and track savings. The page includes installation steps, a local savings check, and benchmark results comparing cost and performance. |
Developer Tools / AI Development | 86 | ↑ +2 | 98 days ago | Details |
|
#729
↑ +2
The Banana Test
A visual benchmark that asks AI coding agents to generate a single-file Three.js animation of a banana plant’s full life cycle, then compares the live results side by side. |
AI Tools / Benchmarking | 86 | ↑ +2 | 100 days ago | Details |
#1012
↓ -6
Agentic CUDA Kernel Optimizer
A LangGraph-based workflow that generates, benchmarks, validates, and iterates CUDA kernels using a C++/CUDA harness. It targets workload-specific optimization with support for NVIDIA research lookup and optional Nsight Compute profiling. |
Developer Tools / AI Development Tools | 84 | ↓ -6 | 19 days ago | Details |
#1021
↓ -6
ROCmFix
A utility for AMD GPU users running local AI on Windows or Linux. It detects the GPU, applies the right HSA_OVERRIDE_GFX_VERSION setting, offers health checks, and benchmarks Vulkan vs. HIP/ROCm for local LLM setups. |
Developer Tools / AI / ML Utilities | 84 | ↓ -6 | 25 days ago | Details |
A benchmark writeup comparing GraphQL-over-MCP and REST-over-MCP setups, showing lower token use and inference cost for GraphQL in agentic tasks. |
Developer Tools / AI Testing & Benchmarks | 84 | ↓ -6 | 28 days ago | Details |

A detailed post from pact0 about testing whether blank AI agents could complete a real product workflow, what failed, and the fixes they shipped after the audit. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 34 days ago | Details |