
AgentDish directory
llm-inference
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#393
↓ -3
tiny-vllm
Open-source C++ and CUDA LLM inference engine inspired by vLLM, with a teaching-focused course that walks through model serving, batching, KV cache, and attention kernels. |
Developer Tools / AI Inference / LLM Serving | 88 | ↓ -3 | 139 days ago | Details |
A research article from Applied Compute on how agentic, tool-using workloads differ from traditional LLM benchmarks, with production observations, workload profiles, and an open-source harness for replaying traces. |
Research / Knowledge Work | 87 | ↓ -153 | 163 days ago | Details |
#610
↑ +2
Quixotic AI / Jinfer
AI inference for the JVM with chat, vision, embeddings, and text-to-speech, plus Java-first building blocks and example snippets. |
Developer Tools / AI / ML Infrastructure | 86 | ↑ +2 | 31 days ago | Details |
#771
↑ +2
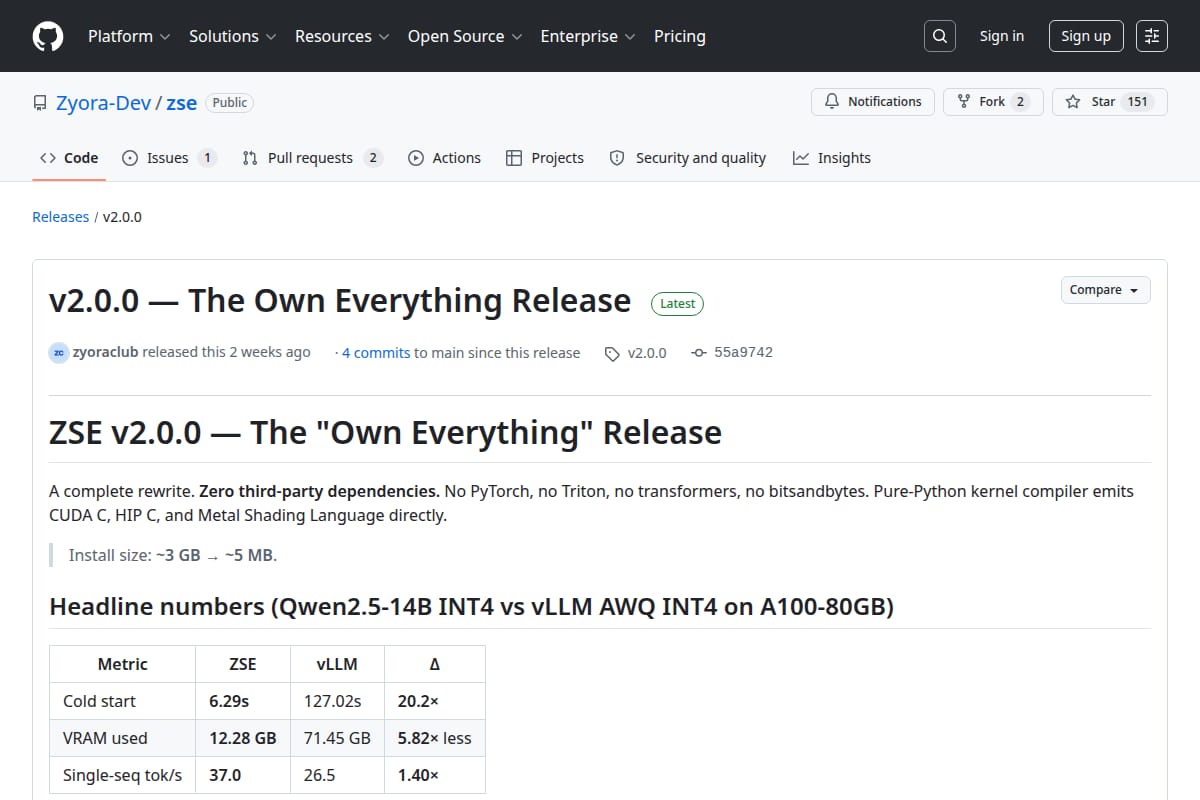
ZSE v2.0.0
A pure-Python LLM inference engine and server with CUDA/HIP/Metal code generation, OpenAI-compatible API support, built-in RAG, and multi-GPU backend support. |
Developer Tools / AI / ML Infrastructure | 86 | ↑ +2 | 136 days ago | Details |
#897
↓ -3
Otlet
Otlet is a Postgres extension for running local LLM inference next to database rows. The README shows SQL examples, model registration, task execution, and an entity-resolution workflow with typed outputs. |
Developer Tools / Databases | 85 | ↓ -3 | 81 days ago | Details |
#927
↓ -3
axiom
Bootable Rust no_std kernel built as an inference substrate for LLMs, with tensor-native memory allocation, layer-boundary scheduling, and streaming-focused runtime primitives. |
Developer Tools / AI Infrastructure | 85 | ↓ -3 | 106 days ago | Details |
#1003
↓ -6
jeva.cpp
A llama.cpp fork that adds a JEV-compatible decision API for Choice, Score, and Noul evaluations while keeping standard LLM inference support. |
Developer Tools / AI/LLM Infrastructure | 84 | ↓ -6 | 18 days ago | Details |
#1178
↓ -6
LLM Inspector
An open-source CLI for inspecting live LLM inference processes on NVIDIA GPUs. It breaks down VRAM usage by component, shows runtime and model details, and projects memory savings from quantization strategies. |
Developer Tools / LLM Inference Observability | 84 | ↓ -6 | 90 days ago | Details |
#1633
↓ -2
ExpertCache
Experimental page-aware Metal runtime and reproducibility harness for running oversized sparse mixture-of-experts models on Apple Silicon. The repo documents GPT-OSS 120B support, performance results on 64 GiB and 16 GiB machines, and the runtime/harness structure. |
Developer Tools / AI / ML Infrastructure | 82 | ↓ -2 | 68 days ago | Details |

#1668
↓ -2
WiFi-LLM
A technical demo that streams Llama-2 weights over Wi‑Fi to run inference on an ESP32 with limited RAM. The repo explains the approach, quickstart steps, performance notes, and the split between ESP32 firmware and a PC host process. |
Developer Tools / AI / ML Infrastructure | 82 | ↓ -2 | 87 days ago | Details |
#1903
↓ -1
Jamesob's guide to running SOTA LLMs locally
A GitHub repository guide to running state-of-the-art LLMs on local hardware, with concrete build notes, cost breakdowns, and runnable configs for large models. |
AI Infrastructure / Local LLMs | 80 | ↓ -1 | 105 days ago | Details |
#1948
↑ +2
Kairo
Open-source research workbench for fail-closed LLM inference routing based on measured GPU workloads. The repo documents Phase 1 results, reproducible experiments, quick-start commands, and a policy that only promotes exact measured workload buckets. |
Developer Tools / AI / ML Infrastructure | 79 | ↑ +2 | 32 days ago | Details |
Google Developers Blog post about integrating DFlash, a diffusion-style speculative decoding framework, into the vLLM TPU ecosystem to improve LLM serving speed on TPU v5p. |
Developer Tools / Code Assistant | 78 | ↓ -384 | 163 days ago | Details |
A DeepSeek paper about DSpark, a full-stack codebase for training and evaluating speculative decoding algorithms to speed up LLM inference. |
Developer Tool / AI Infrastructure | 75 | → 0 | 110 days ago | Details |
A technical blog post from the Cua repository describing a process-scoped Metal capability shim for macOS VMs that improves llama.cpp performance on Apple Silicon, with benchmark results and reproduction details. |
Developer Tools / AI Infrastructure | 74 | ↓ -1 | 66 days ago | Details |
#2431
↓ -70
vLLM-Compile
A public slide deck about vLLM-compile, a project focused on bringing compiler optimizations to LLM inference and speeding up torch.compile for vLLM workflows. |
Developer Tools / Code Assistant | 72 | ↓ -70 | 163 days ago | Details |