
AgentDish directory
evaluation
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#7
↓ -1
Traccia
Traccia is an AI agent observability and governance platform with OpenTelemetry-native tracing, runtime policy enforcement, prompt registry, evals, cost attribution, and compliance evidence export. |
Developer Tools / Code Assistant | 92 | ↓ -1 | 55 days ago | Details |
#89
↓ -2
ForecastOps
Local-first observability and evaluation layer for production forecasts. Captures forecasts, validates them, computes horizon-aware metrics, and serves a read-only local UI for comparing runs. |
Developer Tools / MLOps / Observability | 90 | ↓ -2 | 125 days ago | Details |
|
#170
→ 0
ReactBench
ReactBench is a benchmark for evaluating coding agents on realistic React work, with published scores, cost comparisons, and example tasks focused on production-grade frontend issues. |
Developer Tools / Code Assistant | 89 | → 0 | 92 days ago | Details |
#181
→ 0
Mirrors
Mirrors turns production traces into an isolated, runnable copy of an AI agent’s environment so teams can replay workflows, reproduce bugs, and test changes safely before shipping. |
Developer Tools / AI Agent Testing | 89 | → 0 | 105 days ago | Details |
#268
↓ -3
Understudy
Understudy is a scenario-driven testing framework for AI agents. It simulates multi-turn users, records traces of messages and tool calls, and evaluates agent behavior with deterministic checks, optional LLM judges, and reports. |
Developer Tools / AI Testing | 88 | ↓ -3 | 49 days ago | Details |
#405
↓ -3
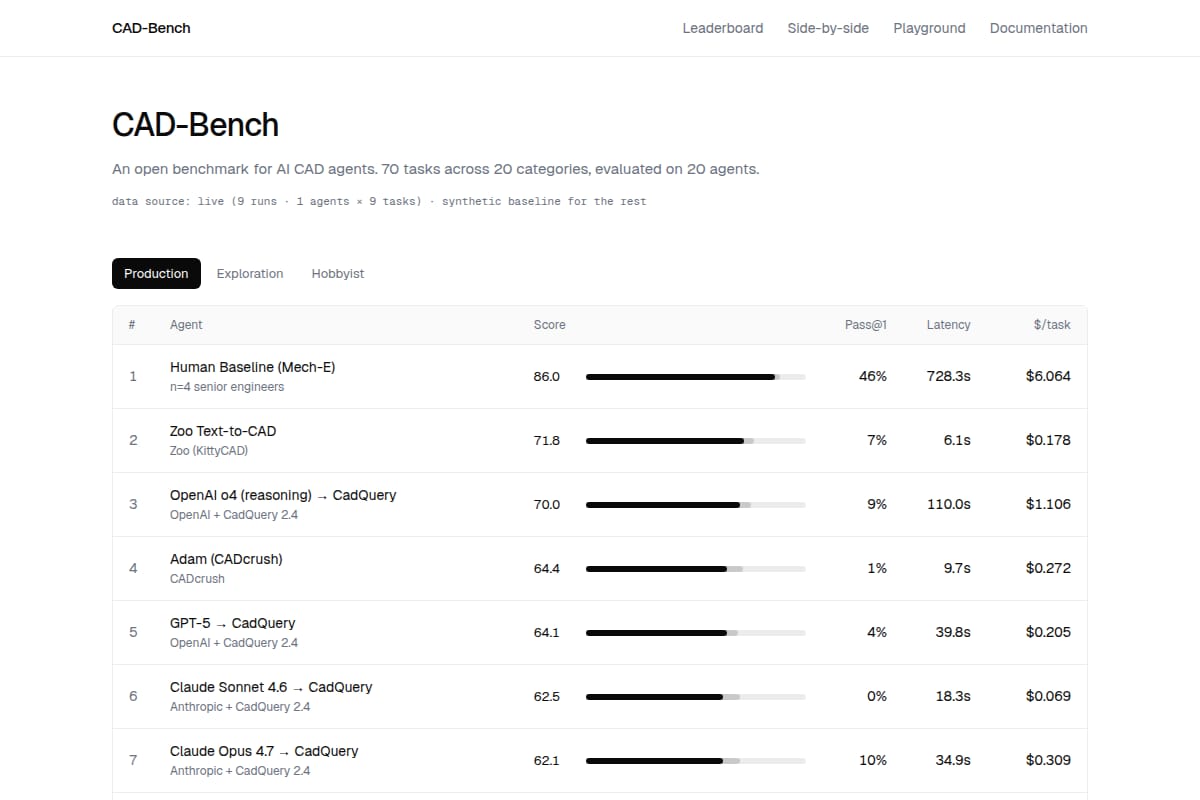
CAD-Bench
An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition. |
Research / Knowledge Work | 88 | ↓ -3 | 160 days ago | Details |
#410
↓ -3
agent-skills-eval
A TypeScript CLI and SDK for testing whether Agent Skills improve model outputs by running with-skill vs baseline evaluations and generating reports. |
Developer Tools / AI Evaluation | 88 | ↓ -3 | 162 days ago | Details |
#444
↓ -4
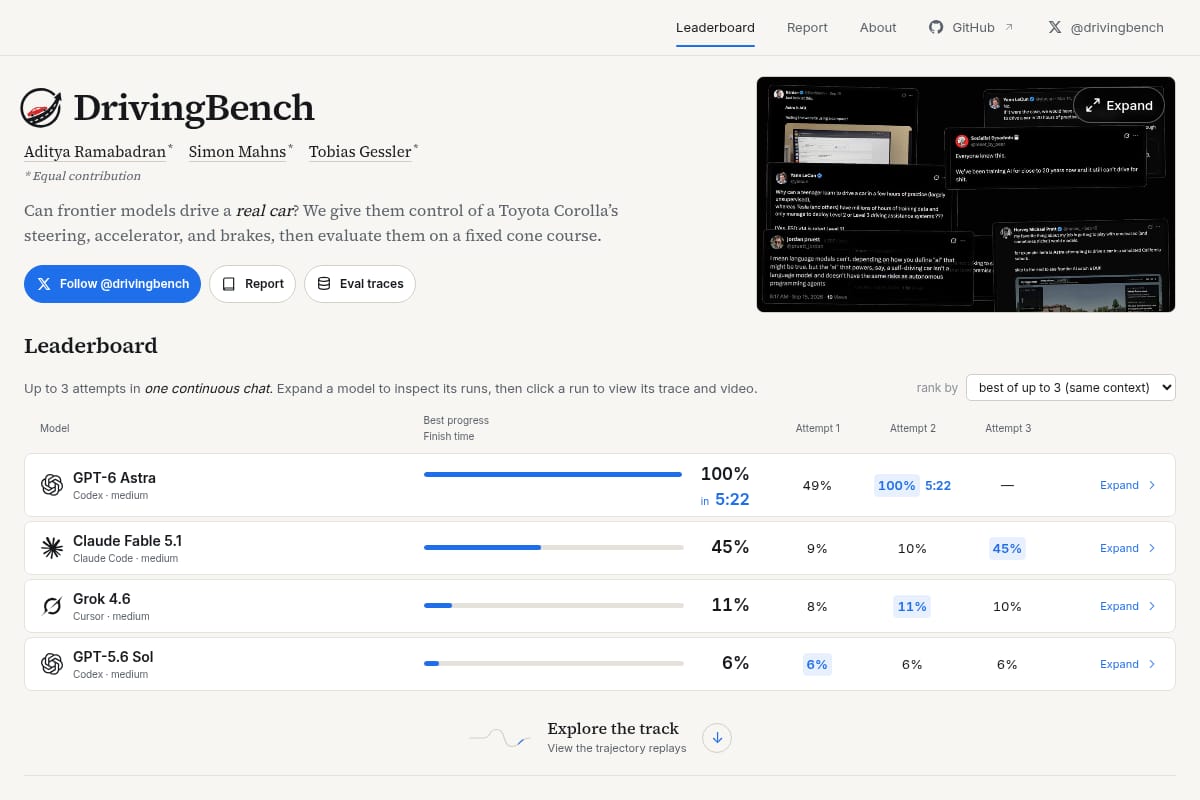
DrivingBench
DrivingBench is a benchmark that tests frontier LLMs on real-world driving tasks in a Toyota Corolla with a cone course, leaderboard, run traces, and replay videos. |
Developer Tools / Benchmarking | 87 | ↓ -4 | 24 days ago | Details |
#446
↓ -4
Skill Crossroads
Evidence-based grading for Claude Code skills, agents, slash commands, MCP configs, and plugins, with file-and-line findings, scorecards, badges, and a local/CI workflow. |
Developer Tools / Code Assistant | 87 | ↓ -4 | 28 days ago | Details |
A Bito research page comparing 29 AI coding models across 60 real engineering tasks, with both quality and cost measured together. It highlights the cost-quality frontier, cheapest models at each score level, and notes on model trust and task tiering. |
AI Research / Benchmarks | 86 | ↑ +2 | 17 days ago | Details |
#825
↑ +1206
Alignment Whack-a-Mole
A research code repository for studying how fine-tuning can trigger verbatim recall of copyrighted books in large language models. It includes preprocessing, fine-tuning, generation, and memorization-evaluation scripts, with setup notes and example data. |
Research / Copywriting | 86 | ↑ +1206 | 164 days ago | Details |
#1007
↓ -6
Using GPT-6 Sol with AI SDK evaluation
A Vercel article showing how to use GPT-6 Sol with the AI SDK evaluation API to assess draft replies, score evidence-based answers, and read structured results in TypeScript. |
Developer Tools / AI SDK / Evaluation | 84 | ↓ -6 | 19 days ago | Details |
#1015
↓ -6
Jev vs. LLMs on 770 AITA posts
A GitHub repo benchmarking TypeSafe’s Jev against Sonnet, GPT-5 nano, and local models on 770 Reddit AITA verdicts, with Brier scores, latency, and cost comparisons. |
AI benchmark / LLM Evaluation | 84 | ↓ -6 | 22 days ago | Details |
#1075
↓ -6
Agentic Determinism Index
Open-source harness for measuring how consistently hosted LLM APIs return the same output across repeated runs and over time, with raw transcripts, scoring, and a static leaderboard generator. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 45 days ago | Details |
#1110
↓ -6
Agent Memory Leaderboard
Public benchmark for comparing agent memory systems, with separate textual and coding tracks, submission flow, documentation, and API guidance. |
Developer Tools / Benchmark | 84 | ↓ -6 | 64 days ago | Details |
#1211
↓ -6
Agent Infra
A curated GitHub resource list for production AI agent infrastructure, covering runtimes, sandboxes, tool protocols, security, observability, and evaluation. |
Developer Tools / AI Infrastructure | 84 | ↓ -6 | 102 days ago | Details |
#1287
↓ -6
DeepSWE
DeepSWE is a benchmark for measuring frontier coding agents on original, long-horizon software engineering tasks. The page shows a leaderboard, methodology overview, task examples, and a full blog explaining the benchmark design and results. |
Developer Tools / AI Benchmarking | 84 | ↓ -6 | 141 days ago | Details |

#1395
↓ -3
Uno
Uno is a research repository for speeding up LLM inference with discrete diffusion and lossless multi-token decoding. The repo includes inference, training, and evaluation code, plus installation steps, checkpoints, and example workflows. |
AI Research / LLM Efficiency / Inference | 83 | ↓ -3 | 42 days ago | Details |
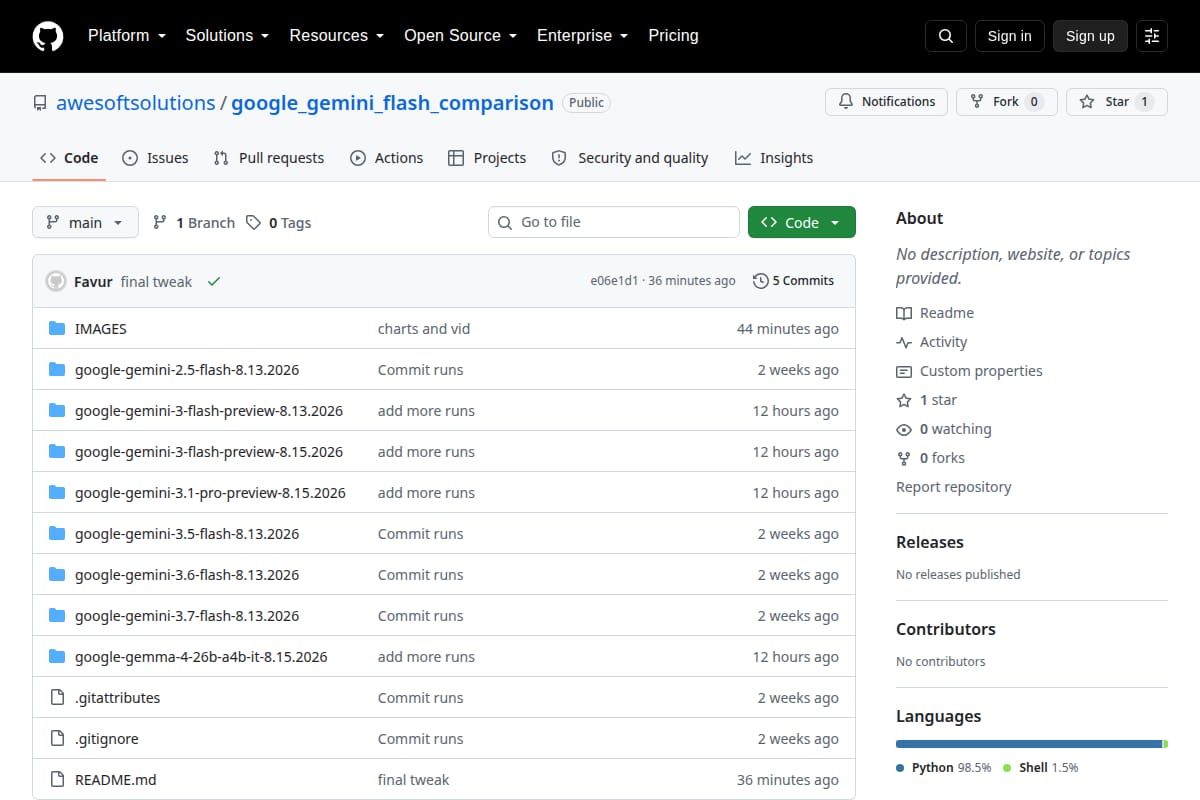
A GitHub repository that publishes a week of controlled runs comparing seven Google models on the same software task, with transcripts, telemetry, screenshots, and scored benchmark artifacts. |
AI Development / Benchmarking | 83 | ↓ -3 | 53 days ago | Details |
Research code for improving agent harnesses through regularized recursive self-improvement, with evaluation, selection, pruning, and domain-specific adapters. |
Developer Tools / AI Agent Frameworks | 82 | ↓ -2 | 17 days ago | Details |

#1666
↓ -2
Ingot
Local-first change control for agent skills, with evidence-gated promotion, SkillOpt optimization, and MCP-based serving of skills. |
Developer Tools / AI Development | 82 | ↓ -2 | 86 days ago | Details |
#1717
↓ -2
clawmark
A local Rust CLI for A/B testing two CLAUDE.md files against a fixed SWE-bench Lite smoke set, with doctor, run, and report commands. |
Developer Tools / AI Benchmarking | 82 | ↓ -2 | 120 days ago | Details |
#1806
↑ +2
iFixAi
Open-source auditing tool for AI agents that checks whether an agent is doing the job it is supposed to do. The repo shows a guided CLI, plugin-based workflows for Claude Code and Codex, and output in JSON, Markdown, and terminal scorecards. |
Developer Tools / Code Assistant | 81 | ↑ +2 | 65 days ago | Details |
#1816
↑ +2
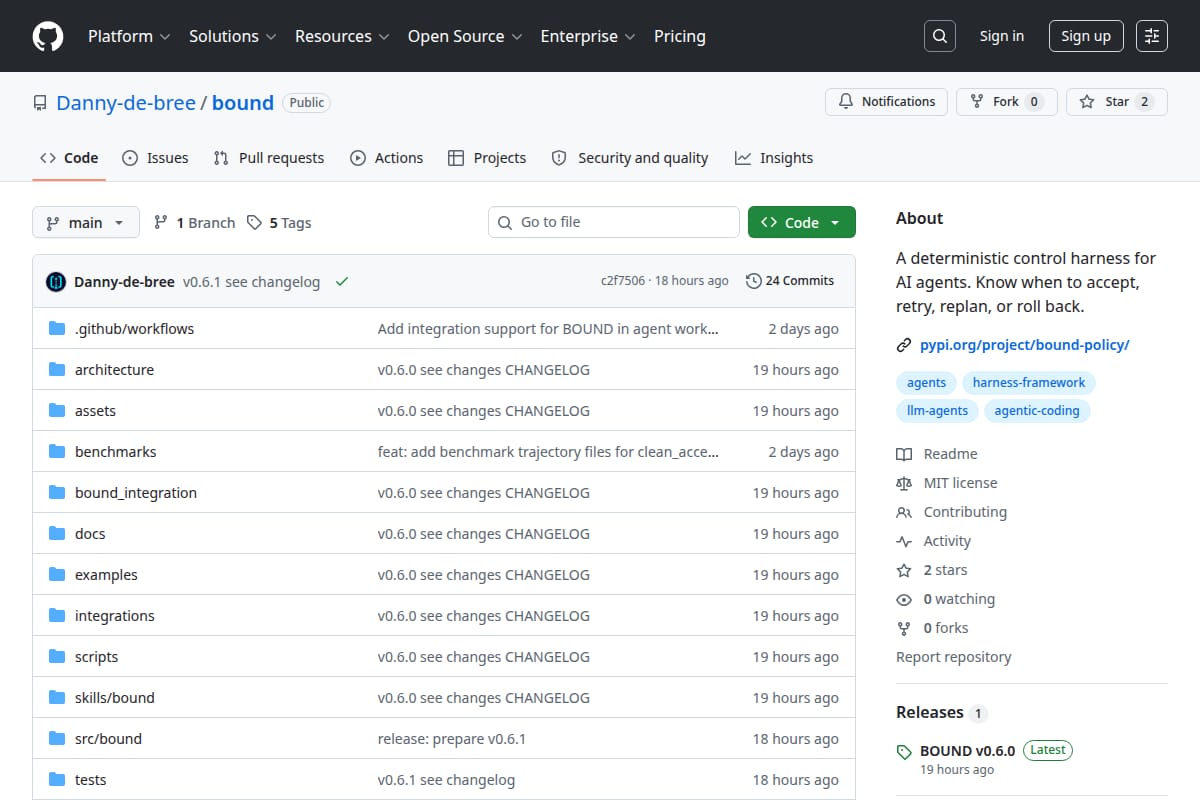
BOUND
BOUND is a deterministic control harness for AI agents. It sits between agent execution and the next decision, using observable evidence to choose ACCEPT, RETRY, REPLAN, or ROLLBACK. |
Developer Tool / AI Agent Framework / Control Harness | 81 | ↑ +2 | 90 days ago | Details |