
AgentDish directory
inference
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#21
↓ -3
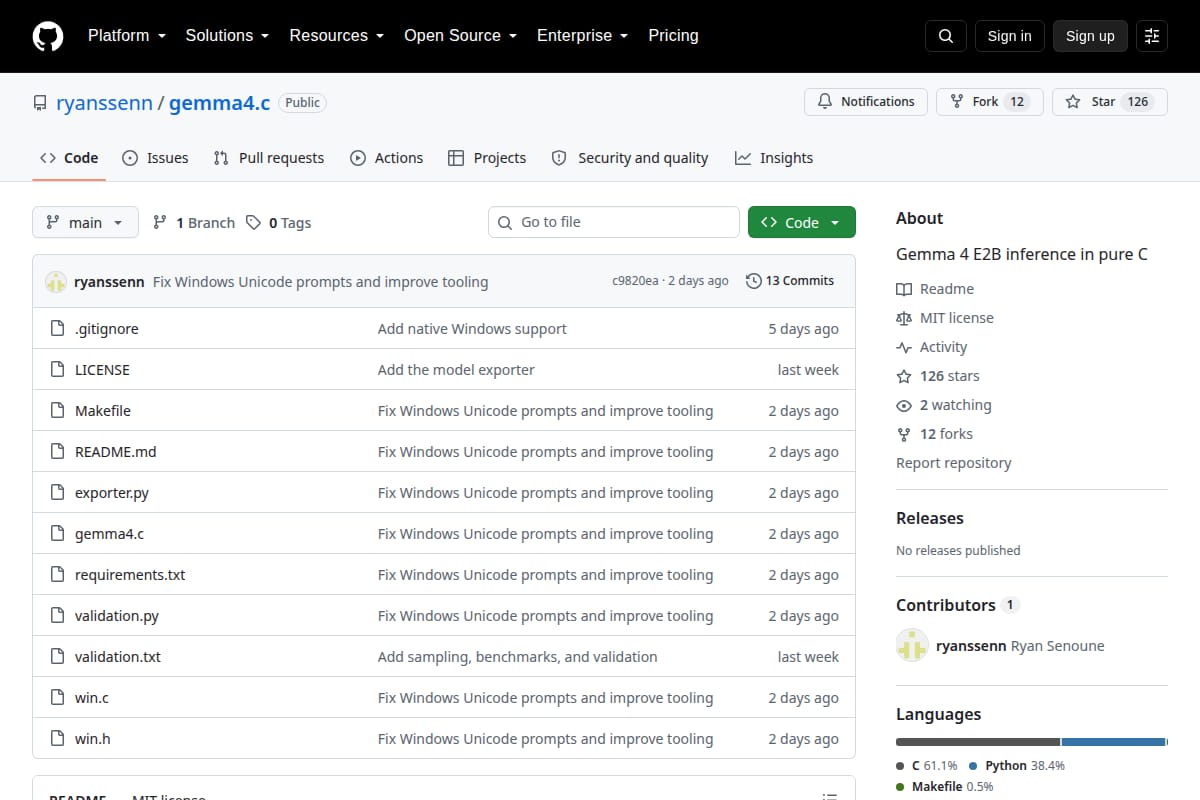
gemma4.c
A pure C runtime for Gemma 4 E2B CPU inference, with export, benchmarking, and numerical validation tools included. |
Developer Tools / Machine Learning / Inference Runtime | 91 | ↓ -3 | 47 days ago | Details |
#39
↓ -2
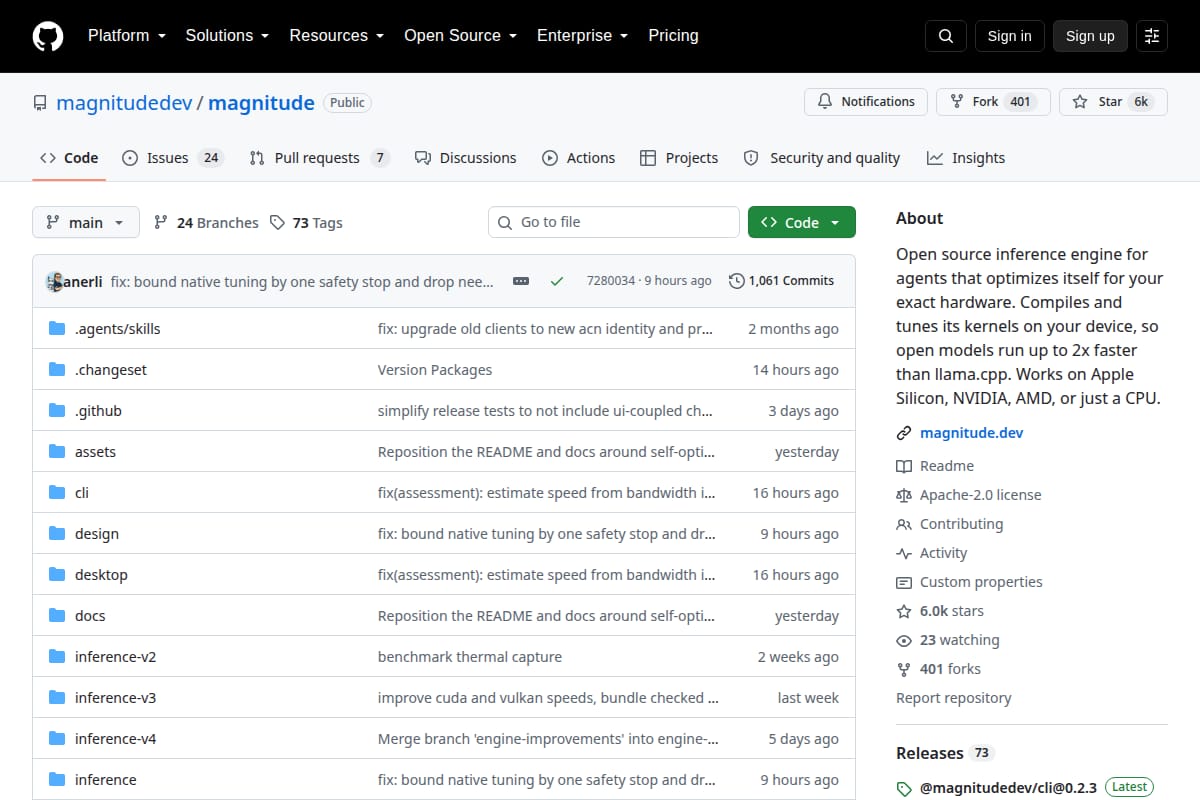
Magnitude
Open source inference engine for agents that self-tunes on the user’s hardware to run open models faster, with desktop app support and one-click connections to popular agents. |
Developer Tool / AI Inference Engine | 90 | ↓ -2 | 14 days ago | Details |
#132
→ 0
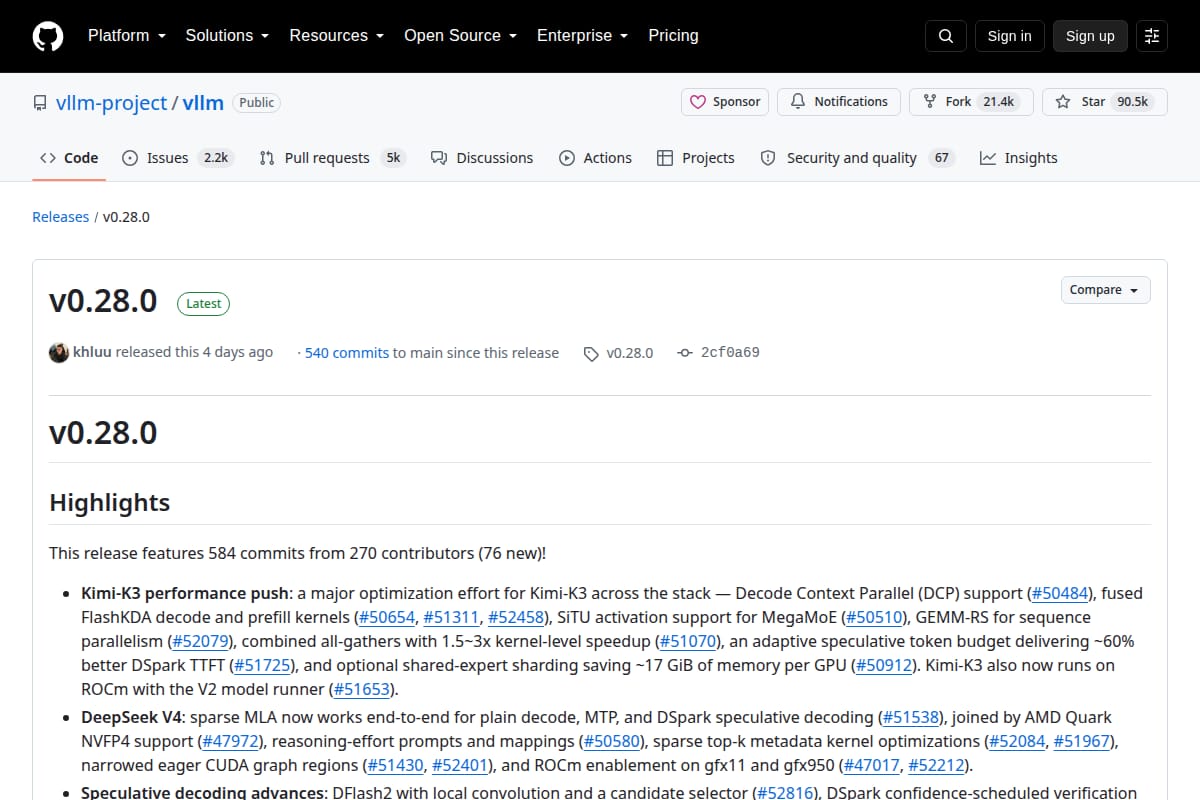
vLLM v0.28.0
Release page for vLLM v0.28.0, a high-throughput and memory-efficient inference and serving engine for LLMs. The snapshot shows release highlights, model support updates, breaking changes, and installable artifacts for PyPI, Docker, ROCm, CPU, and XPU. |
Developer Tools / LLM Serving / Inference | 89 | → 0 | 46 days ago | Details |
#154
→ 0
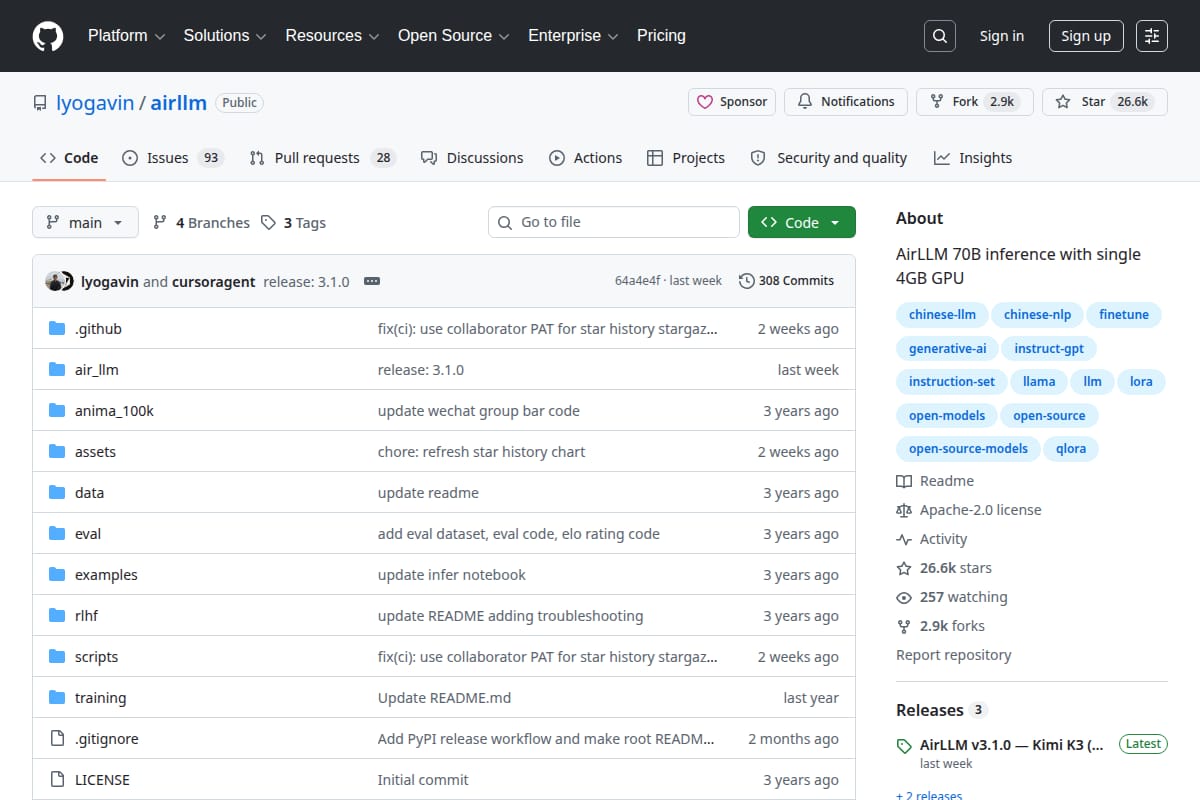
AirLLM
AirLLM is an open-source inference library that aims to run very large language models on small GPUs by decomposing models layer-wise and streaming them during execution. The snapshot shows a detailed README with quickstart code, model examples, supported model notes, and recent update history. |
Developer Tools / AI Inference | 89 | → 0 | 73 days ago | Details |

#210
↓ -104
AutoRound
AutoRound is an open-source quantization toolkit for LLMs and VLMs, focused on high-accuracy low-bit inference across CPU, XPU, CUDA, and multiple deployment backends. |
Developer Tools / AI Infrastructure | 89 | ↓ -104 | 163 days ago | Details |
#219
↓ -3
openTPU
OpenTPU is an open-source AI accelerator project with RTL, ISA, simulator, compiler, profiler, and host software in one repo. The page shows it running real models like Qwen and LFM on a Kintex-7 PCIe card, with detailed performance results and documentation links. |
Developer Tool / AI Hardware / Accelerator | 88 | ↓ -3 | 8 days ago | Details |
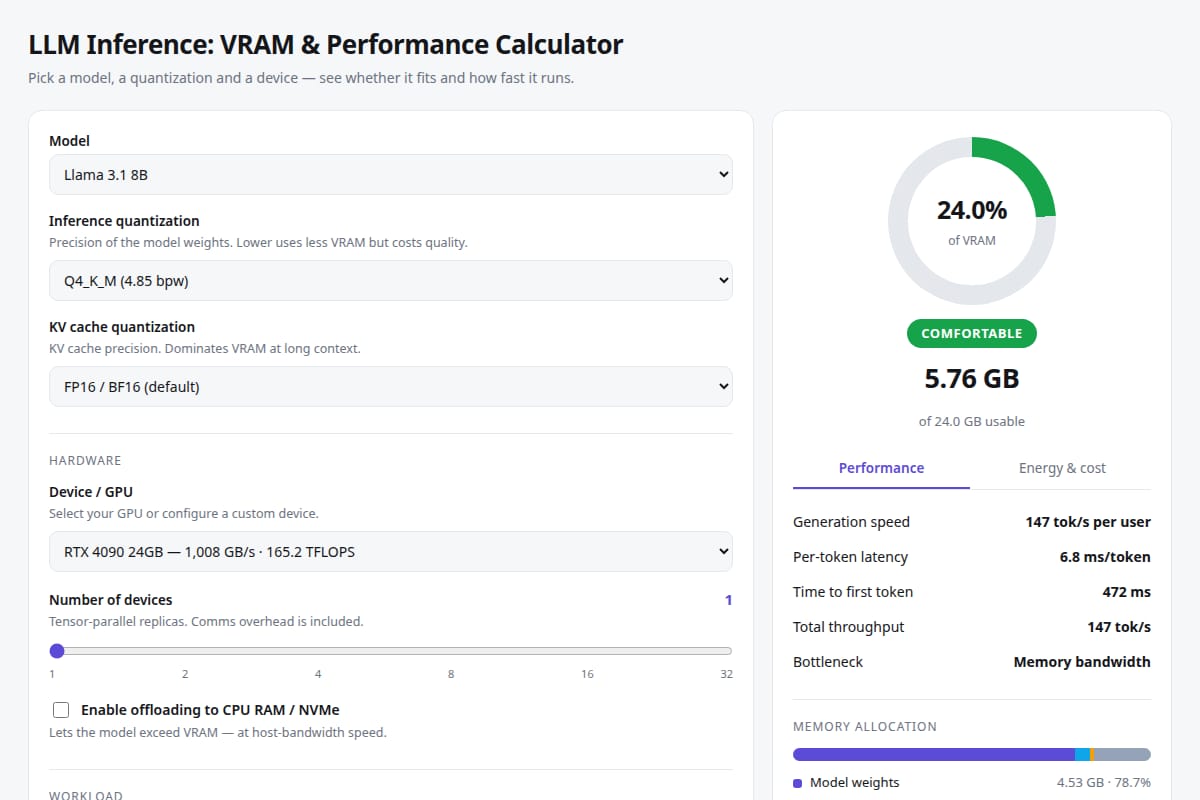
A web calculator for estimating whether local LLMs fit on specific hardware and how fast they may run. It covers VRAM, token throughput, latency, power, and cost across multiple GPUs and devices. |
Developer Tools / Code Assistant | 88 | ↓ -3 | 70 days ago | Details |

#403
↓ -3
grunden.ai
A Swedish AI inference API offering GLM 5.1 on owned H200 hardware in Stockholm, with OpenAI-compatible endpoints, SEK pricing, and an emphasis on EU data residency. |
Developer Tools / API | 88 | ↓ -3 | 156 days ago | Details |
#866
↓ -3
microgpt-c
A pure C implementation for training and running a tiny GPT, with build instructions, sample output, and performance notes for macOS, Linux, and Windows. |
Developer Tool / Machine Learning / AI Framework | 85 | ↓ -3 | 57 days ago | Details |
A technical primer that explains how LLM inference works, covering weights in GPU memory, prefill vs. decode, the KV cache, and batching. |
Writing / Copywriting | 84 | ↓ -6 | 52 days ago | Details |
#1136
↓ -6
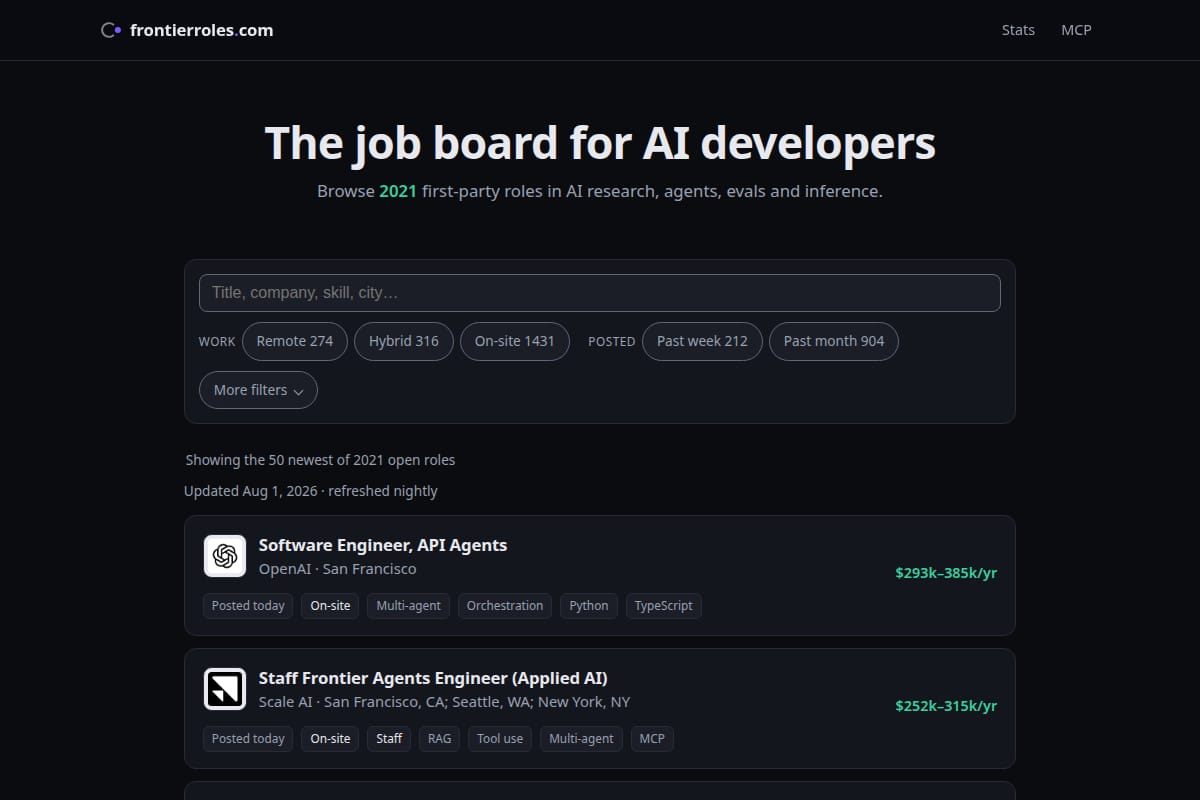
Frontier Roles
A job board focused on AI engineering roles, with first-party listings for RAG, agents, evals, inference, and MCP-related work. The page shows live filters, location and seniority breakdowns, and a nightly refreshed feed of open roles. |
Jobs / AI Engineering Jobs | 84 | ↓ -6 | 75 days ago | Details |

#1271
↓ -6
LLM inference at scale
An open-source handbook for production LLM serving and inference at scale, covering GPU fundamentals, KV cache, batching, quantization, speculative decoding, and engines like vLLM, SGLang, and TensorRT-LLM. |
Developer Tools / AI Infrastructure | 84 | ↓ -6 | 131 days ago | Details |
#1366
↓ -3
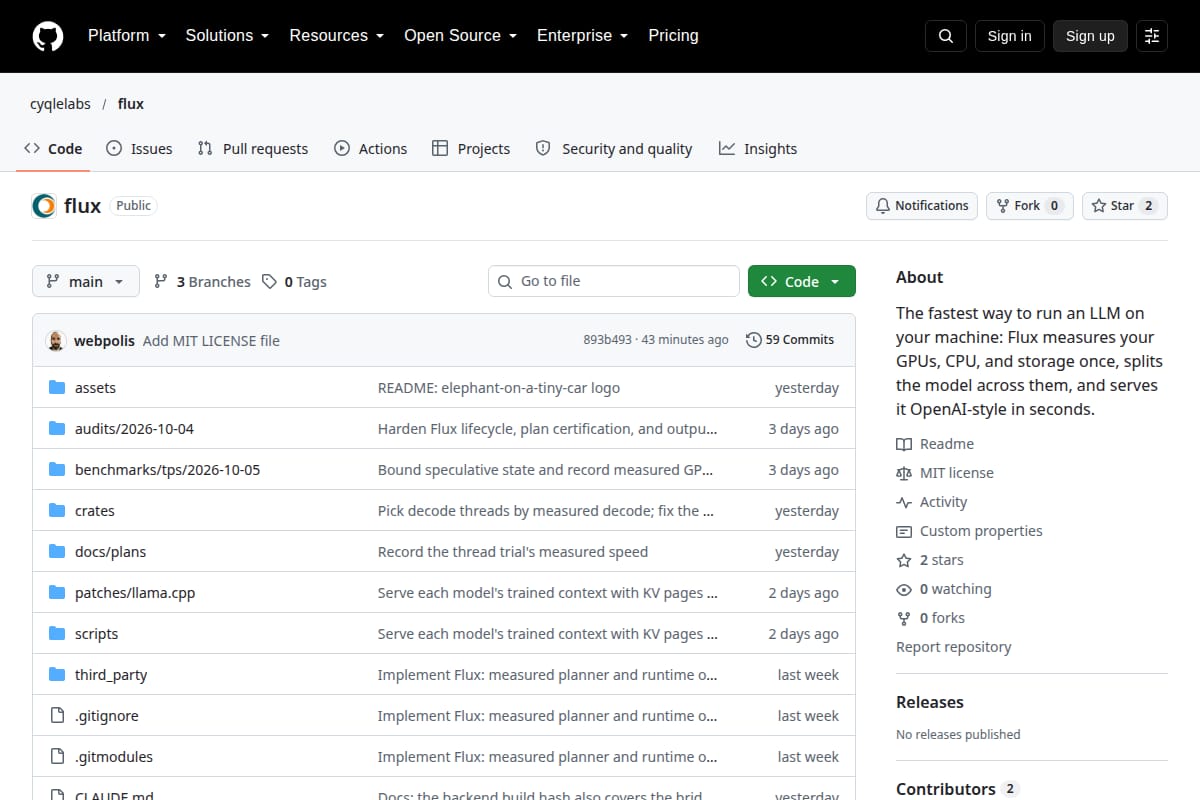
Flux
Flux is a Rust-based LLM inference planner and runtime that measures local hardware, chooses a model placement plan, and serves models behind an OpenAI-compatible API. |
Developer Tools / AI Inference / LLM Serving | 83 | ↓ -3 | 8 days ago | Details |
#1376
↓ -3
AI Performance Engineering
A curated GitHub resource list for learning AI performance engineering, covering GPU fundamentals, kernel optimization, inference engines, and distributed inference. |
AI/ML Resources / Performance Engineering | 83 | ↓ -3 | 13 days ago | Details |

#1395
↓ -3
Uno
Uno is a research repository for speeding up LLM inference with discrete diffusion and lossless multi-token decoding. The repo includes inference, training, and evaluation code, plus installation steps, checkpoints, and example workflows. |
AI Research / LLM Efficiency / Inference | 83 | ↓ -3 | 41 days ago | Details |
#1601
↓ -2
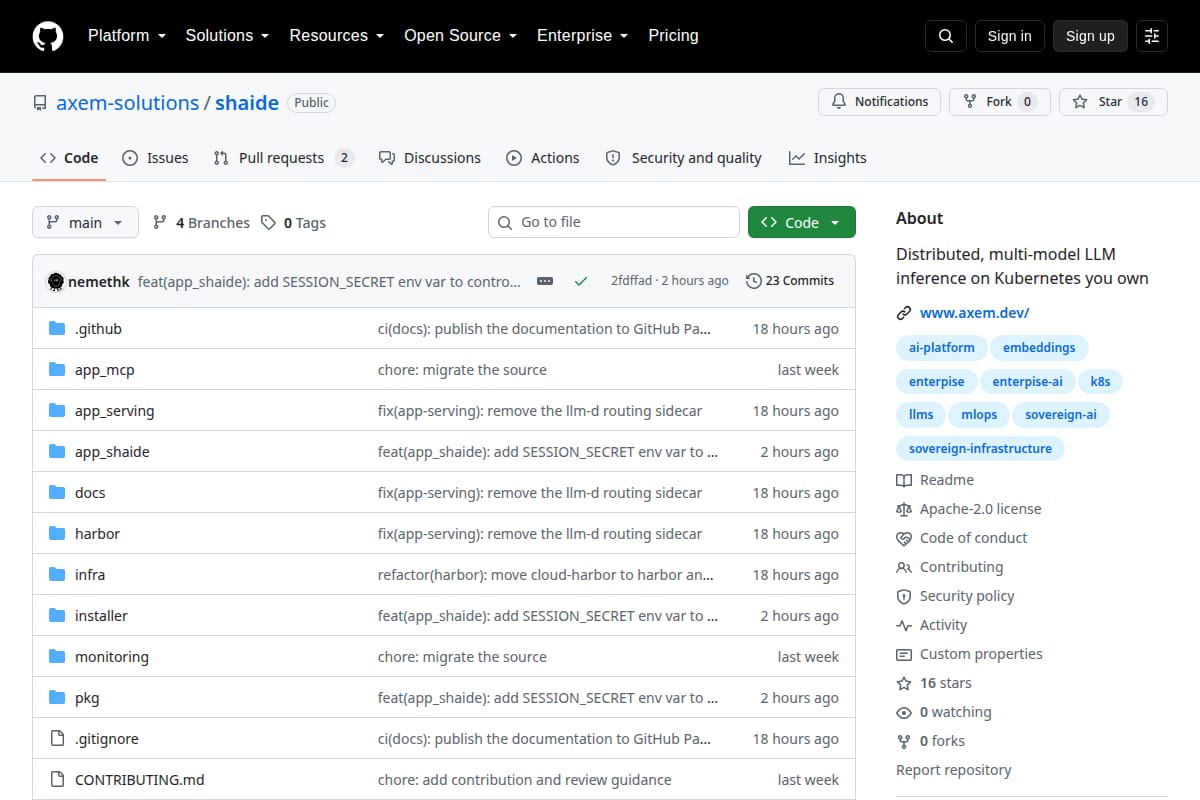
shaide
Self-hosted, Kubernetes-native platform for distributed multi-model LLM inference. It includes an OpenAI-compatible API, installer flow, and infrastructure-as-code deployment with support for air-gapped environments. |
AI Infrastructure / LLM Serving | 82 | ↓ -2 | 44 days ago | Details |
#1812
↑ +2
Scalattice
Scalattice is an inference API and hosting platform that lets developers point the OpenAI SDK at its OpenAI-compatible endpoint with minimal code changes. The page includes Python and curl examples, model IDs, pricing references, and basic troubleshooting. |
Developer Tools / API | 81 | ↑ +2 | 80 days ago | Details |

#1996
↑ +2
tiny-vLLM AMD GPU support via HIP
A pull request adding AMD GPU support to tiny-vLLM through ROCm/HIP while keeping the existing CUDA build path unchanged. The snapshot describes the compatibility header, CMake option, architecture selection, and validation on multiple AMD GPUs. |
Developer Tool / LLM inference engine | 79 | ↑ +2 | 108 days ago | Details |
#2026
↓ -257
Bonsai 1.7B: Apple Silicon Optimized Build
An Apple Silicon–optimized inference build of Bonsai 1.7B with custom Metal kernels, benchmark results, quick-start instructions, and a bundled OpenAI-compatible server. |
Developer Tools / Code Assistant | 79 | ↓ -257 | 162 days ago | Details |
#2060
↑ +6
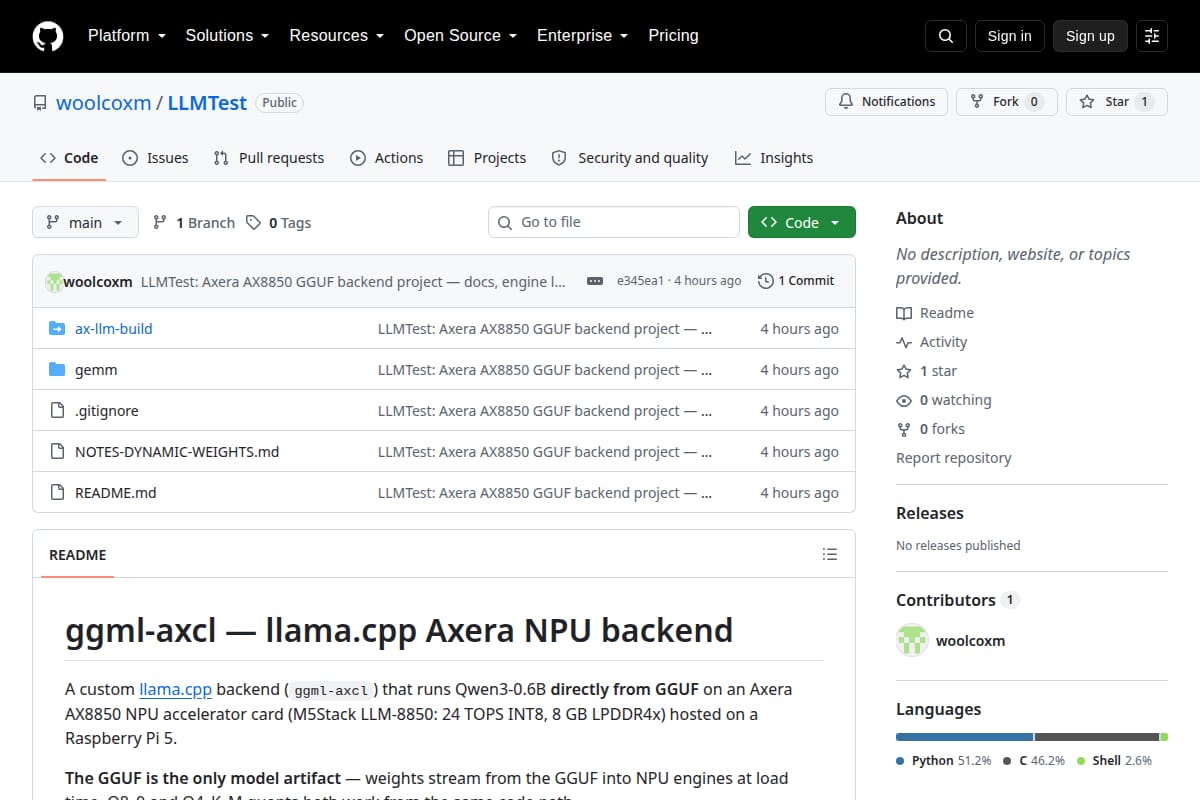
Axera AX8850 LLM running ggufs
A GitHub repository for a custom llama.cpp backend that runs Qwen3-0.6B GGUF models on an Axera AX8850 NPU accelerator, with build/run notes, environment flags, architecture details, and test status. |
Developer Tools / Code Assistant | 78 | ↑ +6 | 50 days ago | Details |
#2310
↓ -1
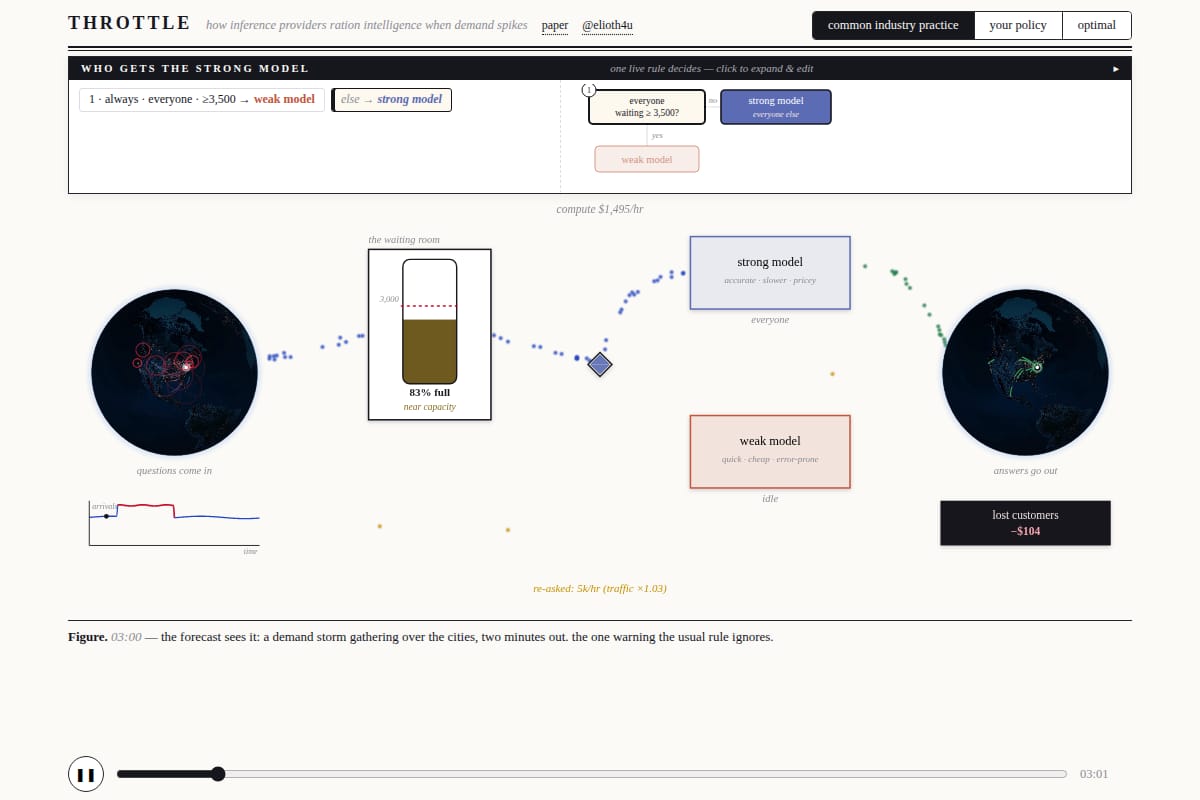
THROTTLE
An interactive simulation about how inference providers ration access to stronger LLMs when demand spikes. Users can compare the default industry rule with their own policy and explore who gets the strong model. |
AI Product / LLM Routing / Inference Management | 74 | ↓ -1 | 48 days ago | Details |