
AgentDish directory
LLM evaluation
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1010
↓ -6
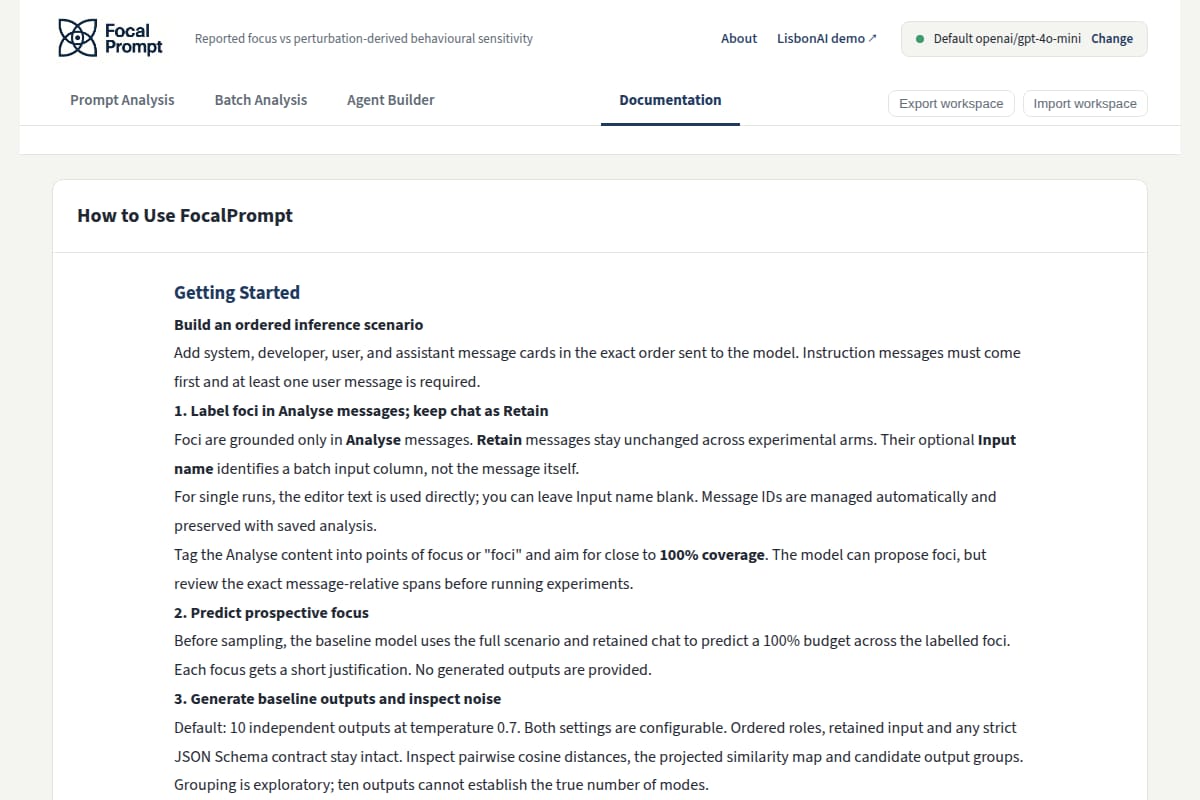
Focal Prompt
Focal Prompt is an analysis lab for studying how prompts and prompt sections influence model behavior. It includes focus labeling, prospective and retrospective focus prediction, baseline output sampling, ablation tests, batch analysis, and an agent builder. |
AI Developer Tool / Prompt Analysis | 84 | ↓ -6 | 19 days ago | Details |
#1077
↓ -6
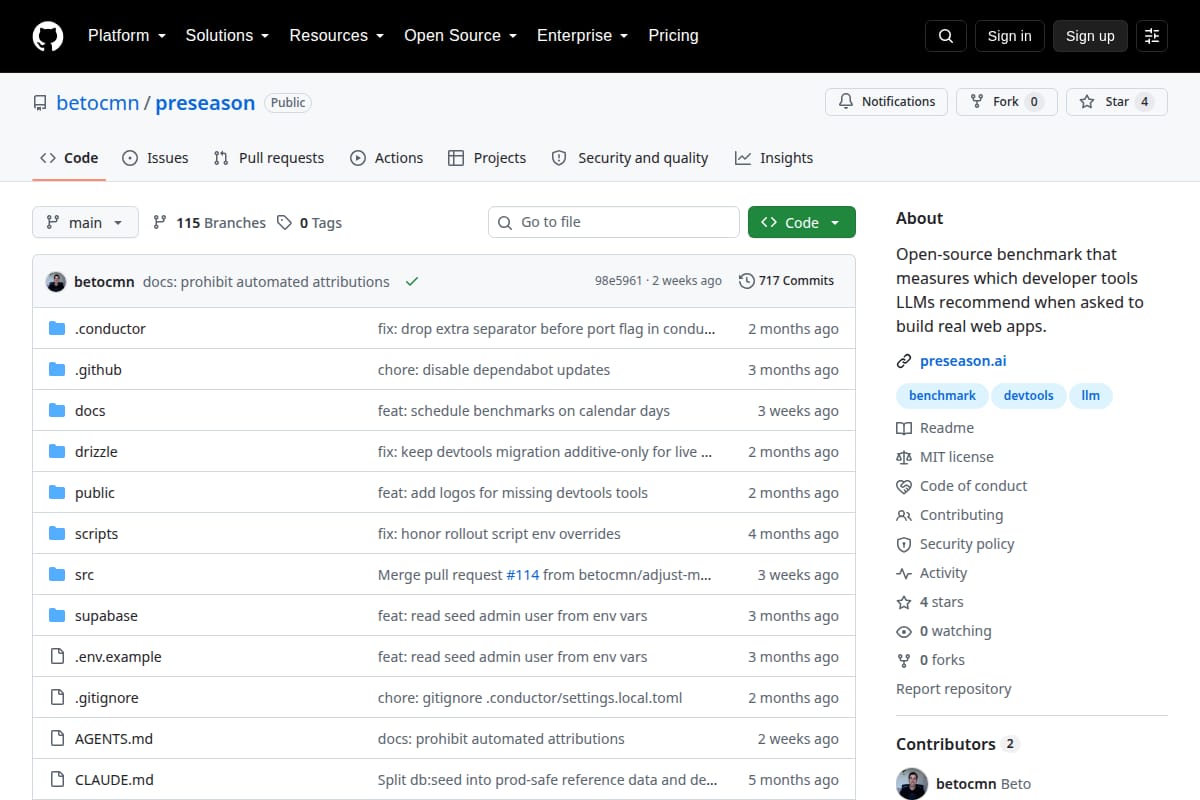
Preseason
Open-source benchmark that measures which developer tools LLMs recommend when asked to build real web apps. It runs fixed prompts against a panel of models, parses the tool recommendations, and publishes rankings and head-to-head comparisons. |
Developer Tools / AI Benchmarking | 84 | ↓ -6 | 45 days ago | Details |
#1089
↓ -6
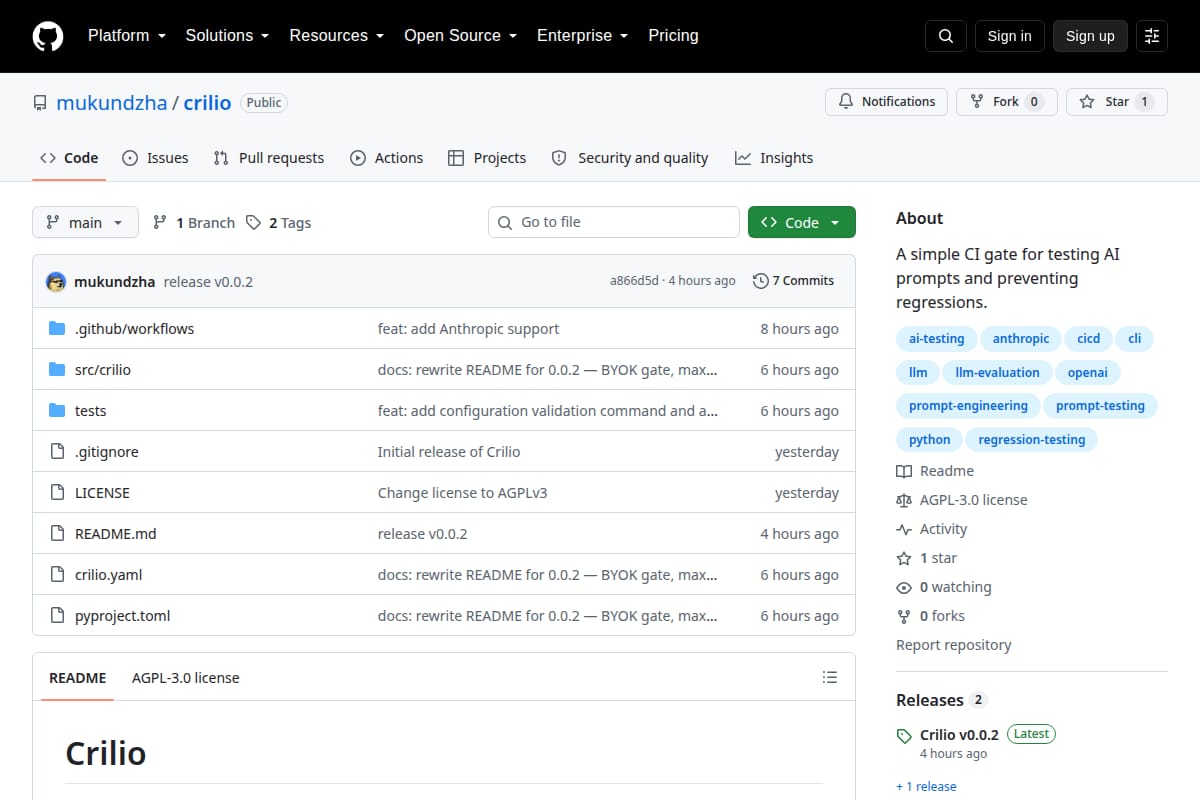
Crilio
Crilio is a Python CLI and CI gate for testing AI prompts and catching regressions before they ship. It versions prompt tests in crilio.yaml, runs model calls, uses a judge model to score responses, and can block pull requests in GitHub Actions when checks fail. |
Developer Tools / AI Testing & Evaluation | 84 | ↓ -6 | 51 days ago | Details |
#1113
↓ -6
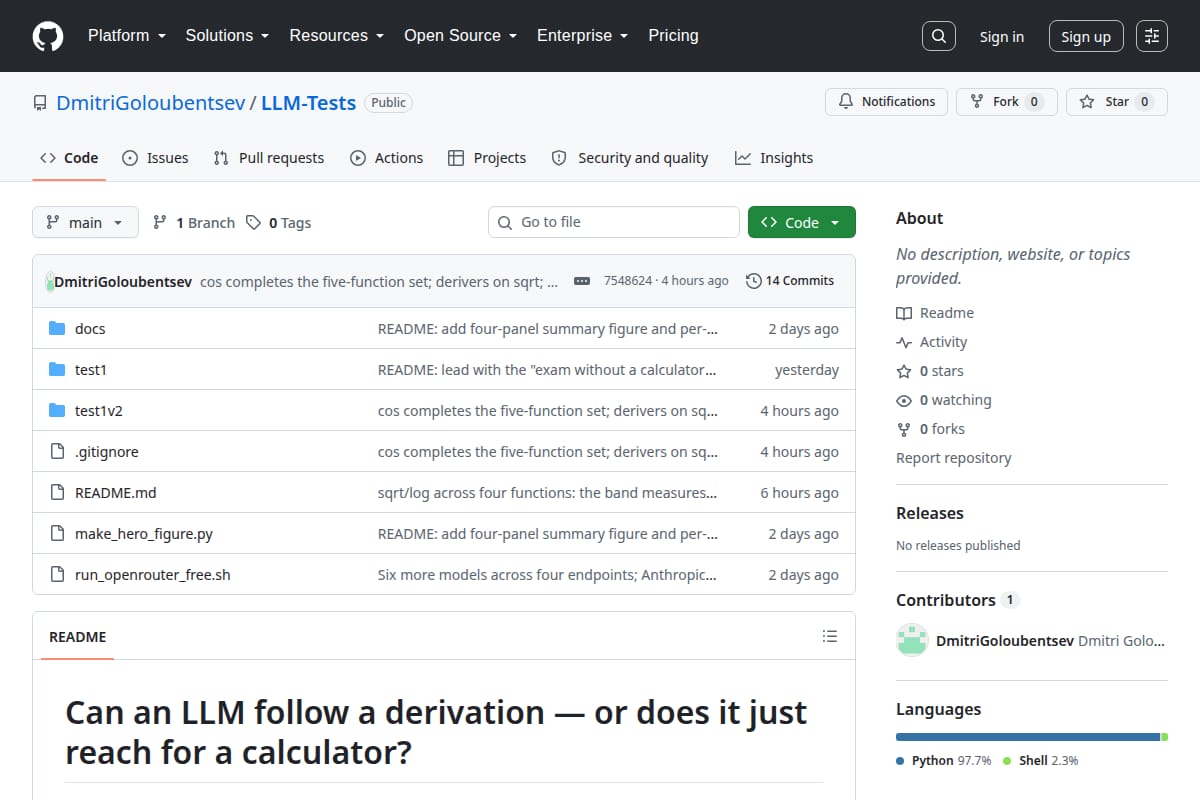
LLM-Tests
An open-source benchmark for testing whether LLMs can follow long arithmetic derivations without using tools. It compares models on recall-proof inputs, logs digit accuracy, and reports results across multiple endpoints and model families. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 64 days ago | Details |
#1849
↓ -73
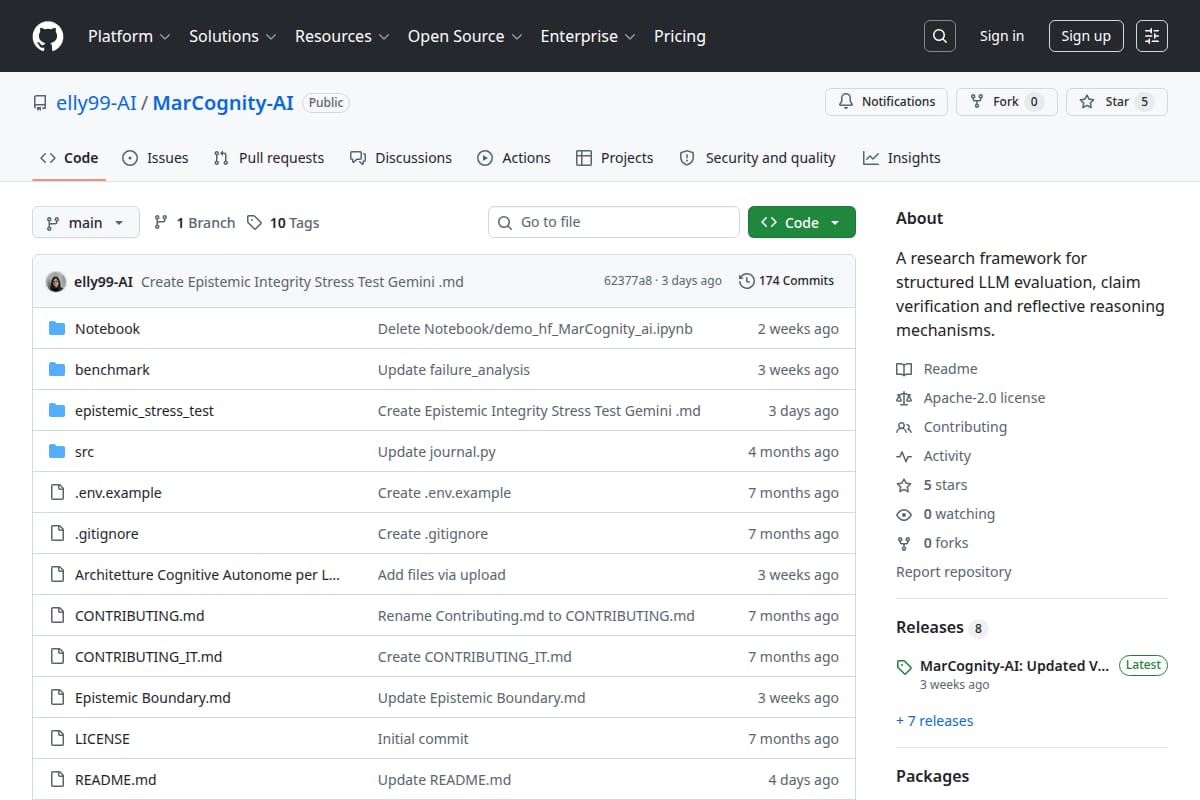
MarCognity-AI
An open-source research framework for structured LLM evaluation, claim verification, and source-grounded reflective reasoning. The repo describes modular components for retrieval, semantic scoring, skeptical claim checking, and benchmark-style epistemic assessment. |
AI Research / Evaluation / Verification Framework | 81 | ↓ -73 | 163 days ago | Details |

#2000
↑ +2
AdvertBench
AdvertBench is a web app for ranking AI-generated image ad sets with Elo voting. The page shows head-to-head ad comparisons, a leaderboard, and a sample prompt for generating ads, making the product purpose easy to understand. |
Developer Tools / Code Assistant | 79 | ↑ +2 | 116 days ago | Details |
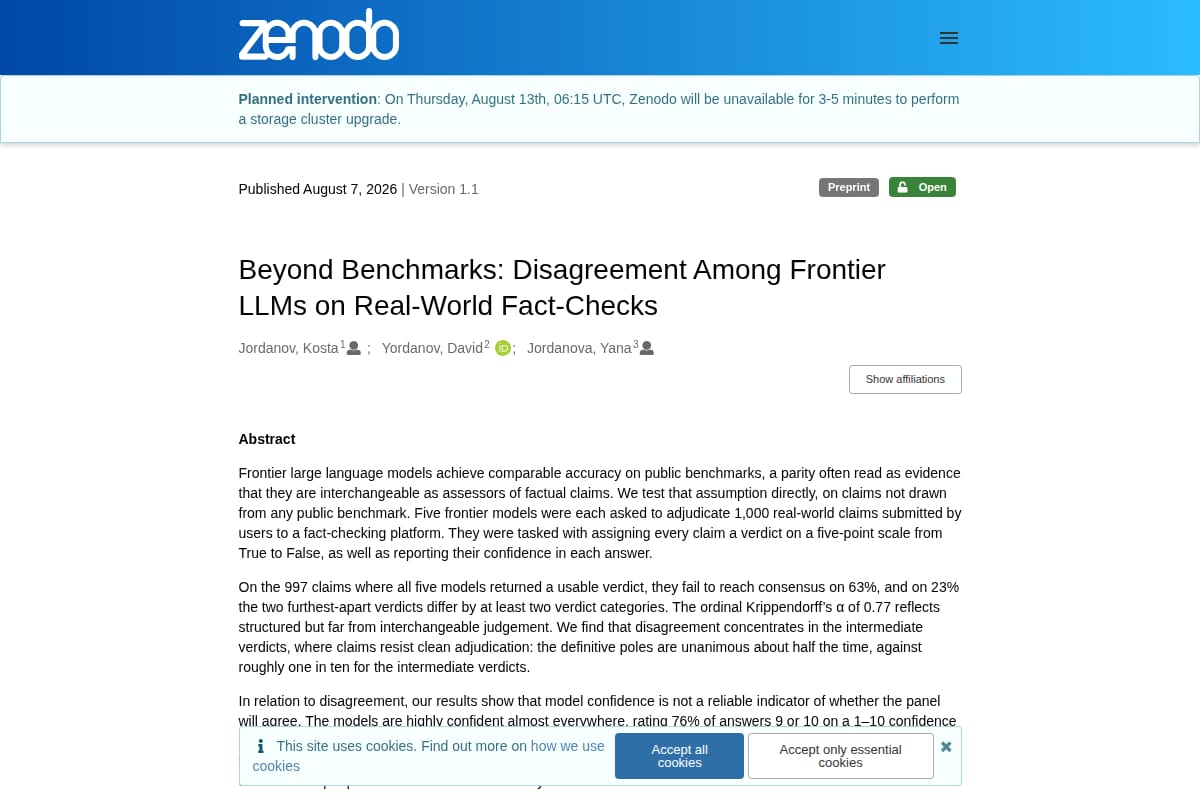
A research preprint and dataset on how five frontier LLMs disagree when judging 1,000 real-world fact-check claims, with accompanying corpus, raw results, and code repository. |
Research / LLM Evaluation | 76 | ↓ -1 | 64 days ago | Details |
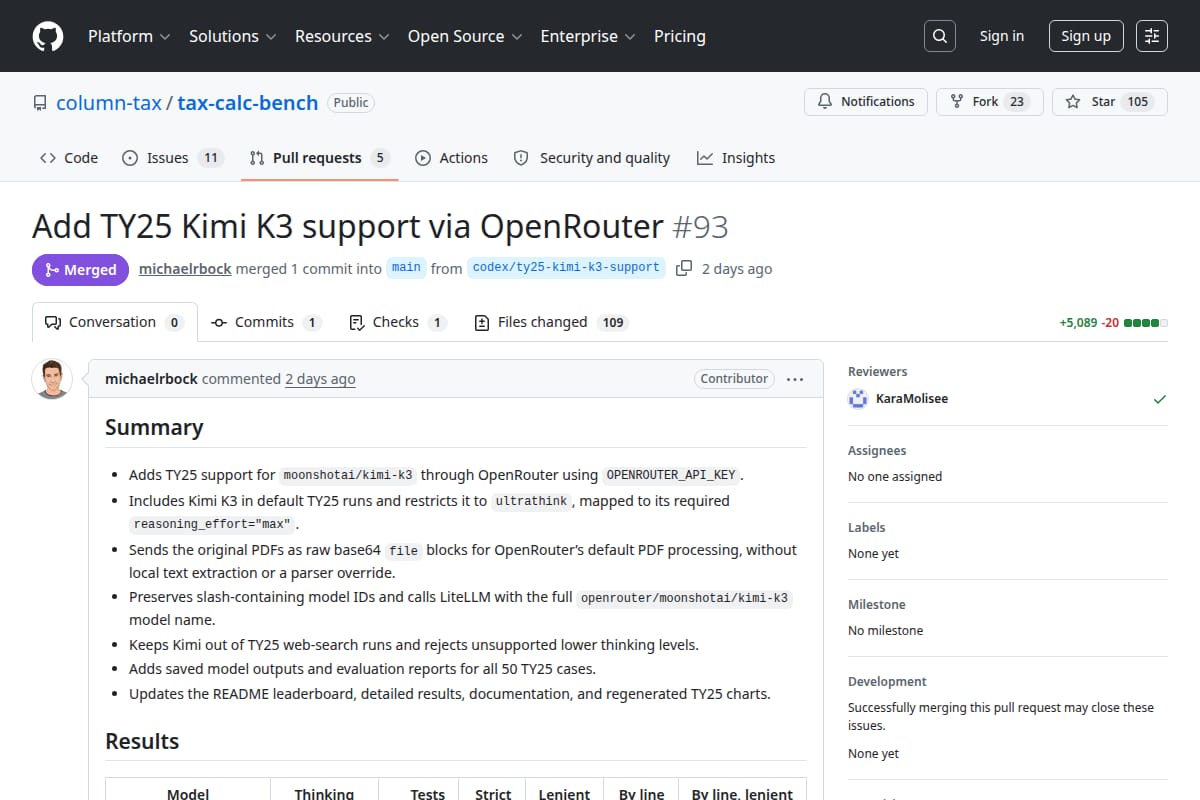
Pull request adding TY25 support for moonshotai/kimi-k3 in TaxCalcBench through OpenRouter. The snapshot shows benchmark wiring, PDF handling details, saved outputs and evaluation reports, and regenerated charts/results for the full TY25 set. |
AI Developer Tool / Benchmarking / evaluation | 76 | ↓ -1 | 85 days ago | Details |

#2281
→ 0
Giskard
Giskard presents an AI red-teaming and continuous evaluation platform focused on finding hallucinations, security issues, and agent vulnerabilities. The page explains how it compares tools for agent-level testing, regression checks, and guardrail workflows. |
Security / AI Red Teaming | 75 | → 0 | 113 days ago | Details |