Research / Knowledge Work

Deterministic Inference Did Not Make Our Pipeline Deterministic

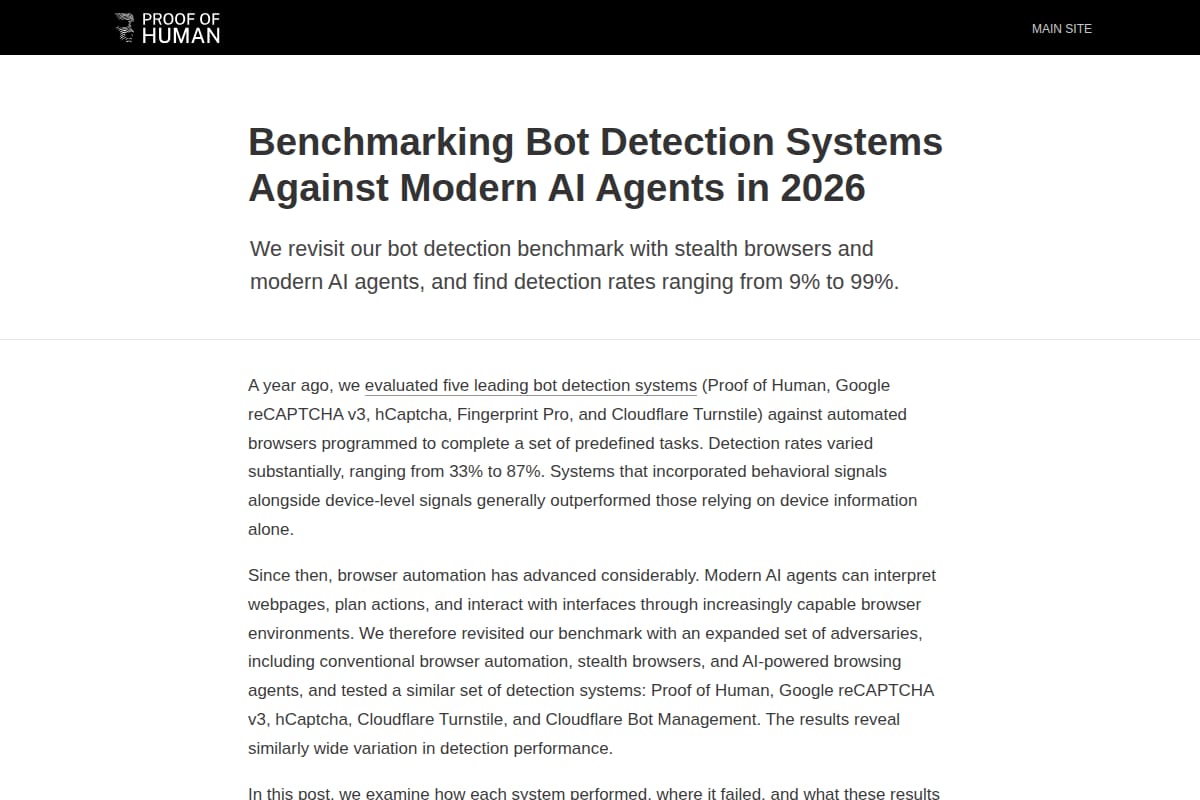
CTGT’s research post shows how deterministic LLM serving can still produce inconsistent pipeline outcomes, and introduces Concordance, an Apache 2.0 instrument for tracing where AI workflows diverge. The page includes the problem setup, benchmark details, findings, limitations, and a linked repo for reproduction.

Clear25/30
Useful27/30
Specific15/20
Complete15/20
Deterministic Inference Did Not Make Our Pipeline Deterministic screenshot

Why it was accepted

This is a substantive AI research page with clear evidence of an AI-related tool and project context. It explains a real failure mode in LLM pipelines, describes what Concordance measures, gives benchmark and fix details, and points to a public GitHub repository with protocol, harnesses, and run data. That is enough for a useful directory listing.
Weakness

The page is mainly a research write-up, so visitors still cannot tell the tool’s broader product shape, packaging, or integration surface from the crawl alone. There is no visible install guide, API reference, or screenshots of Concordance in use beyond the repo mention.

Review status

5 days ago #1647 ↓ -2

Last evaluated 5 days ago. Current rank #1647. Down 2 spots in the rankings.

Score history

82

Related listings

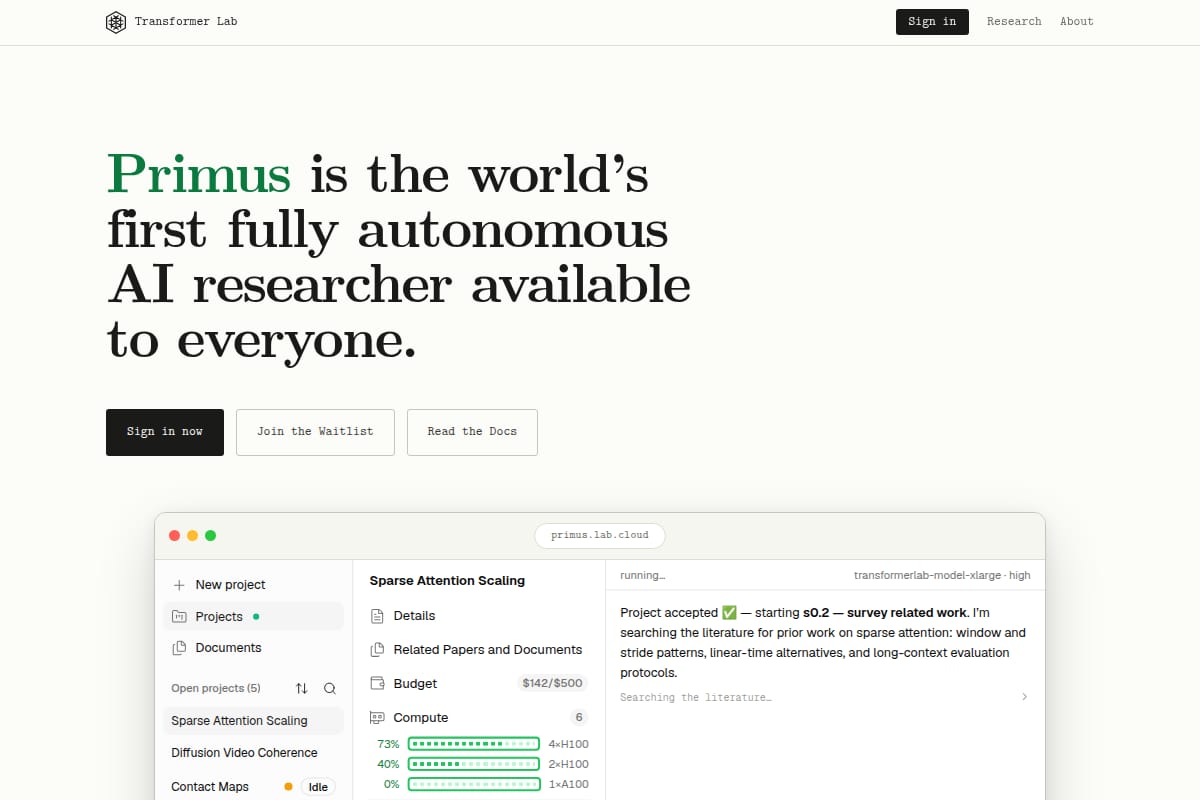
Primus AI Researcher – Free screenshot

Research / Knowledge Work

Primus is an autonomous AI researcher that hypothesizes, reads papers, writes code, runs experiments on compute, and drafts research papers. The page shows example tasks, published-paper claims, waitlist access, and positioning for ML research workflows.

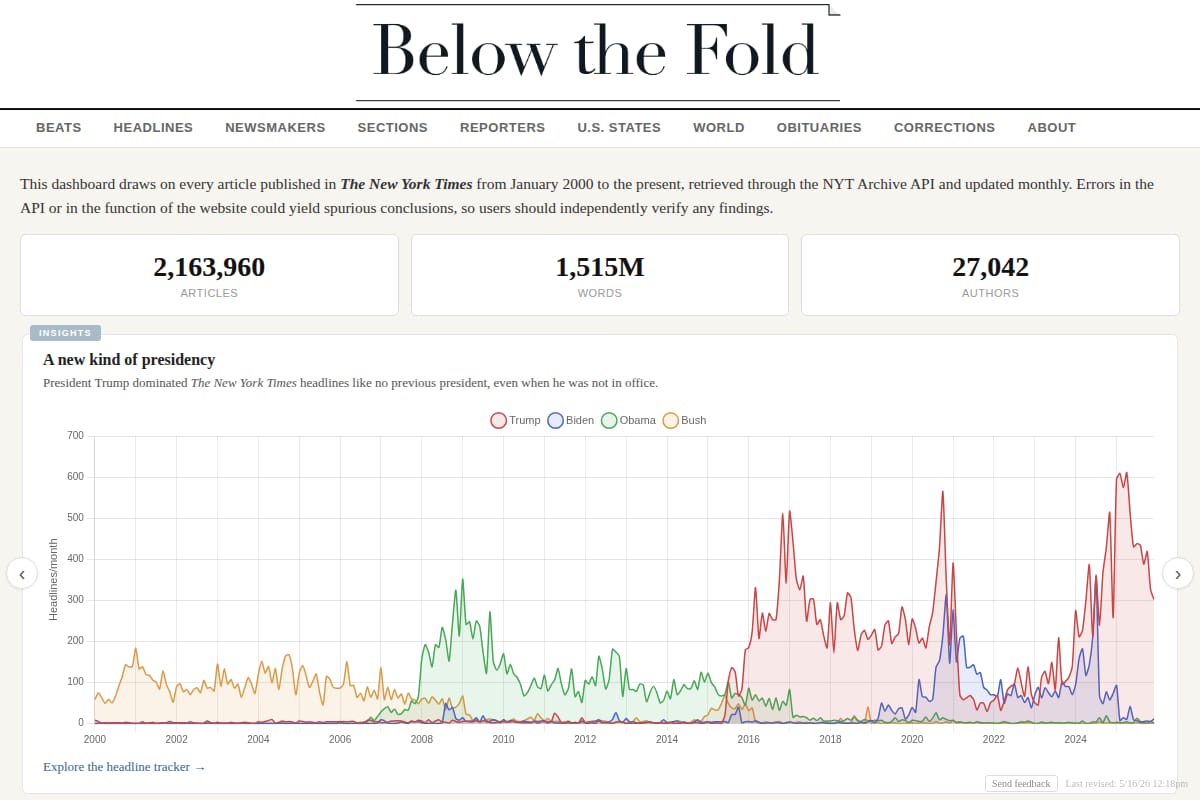
Below the Fold — A New York Times X-Ray Dashboard screenshot

Research / Data Visualization

An interactive dashboard that analyzes New York Times coverage since 2000 using the NYT Archive API, with views for reporters, beats, sections, subjects, geography, obituaries, and corrections.

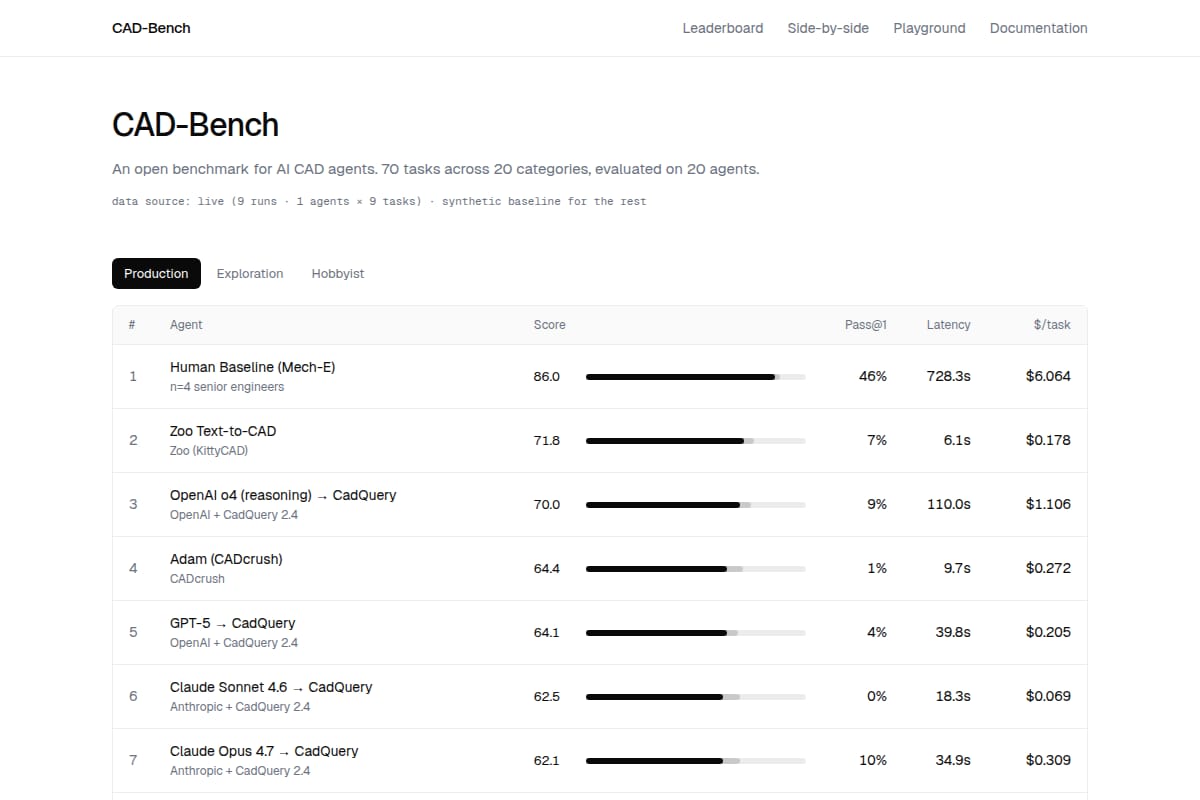
CAD-Bench screenshot
#436 CAD-Bench
88

Research / Knowledge Work

An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition.