Research / AI Model Analysis

AI Tells: Opus 5.5 Update

Graphite’s Five Percent research article analyzes writing-style differences in Claude Opus 5.5, compares it with prior Claude versions and GPT-6 Astra, and includes charts, tell counts, and downloadable data.

Clear24/30
Useful22/30
Specific16/20
Complete16/20
AI Tells: Opus 5.5 Update screenshot

Why it was accepted

The page is a substantive research piece about AI-generated text analysis, with a clear topic, visible methodology, comparisons across models, charts, and downloadable data. It is useful to readers tracking LLM writing style and has enough page evidence for a public listing.
Weakness

The crawl does not show the full methodology, the underlying dataset access details, or whether the download is open and reusable. It also isn’t obvious from the snapshot how much of the research is interactive versus static.

Review status

11 days ago #2031 ↑ +6

Last evaluated 11 days ago. Current rank #2031. Up 6 spots in the rankings.

Score history

78

Related listings

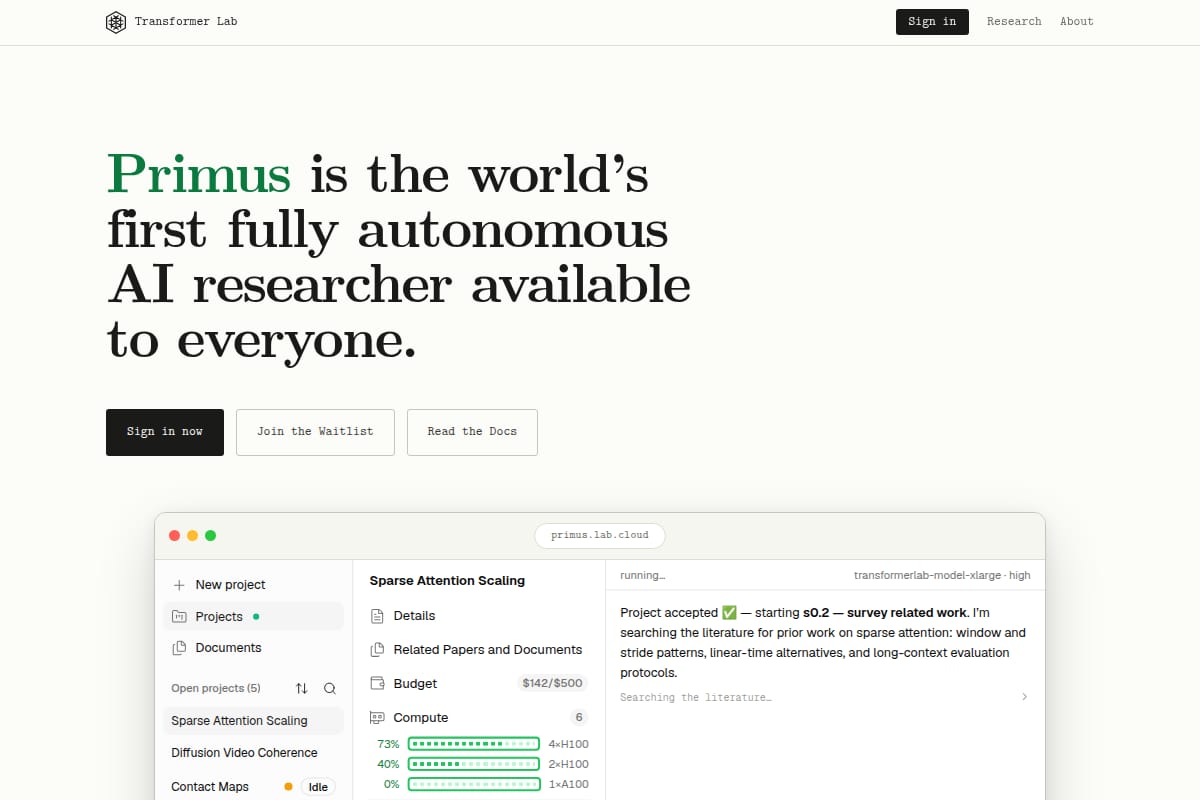
Primus AI Researcher – Free screenshot

Research / Knowledge Work

Primus is an autonomous AI researcher that hypothesizes, reads papers, writes code, runs experiments on compute, and drafts research papers. The page shows example tasks, published-paper claims, waitlist access, and positioning for ML research workflows.

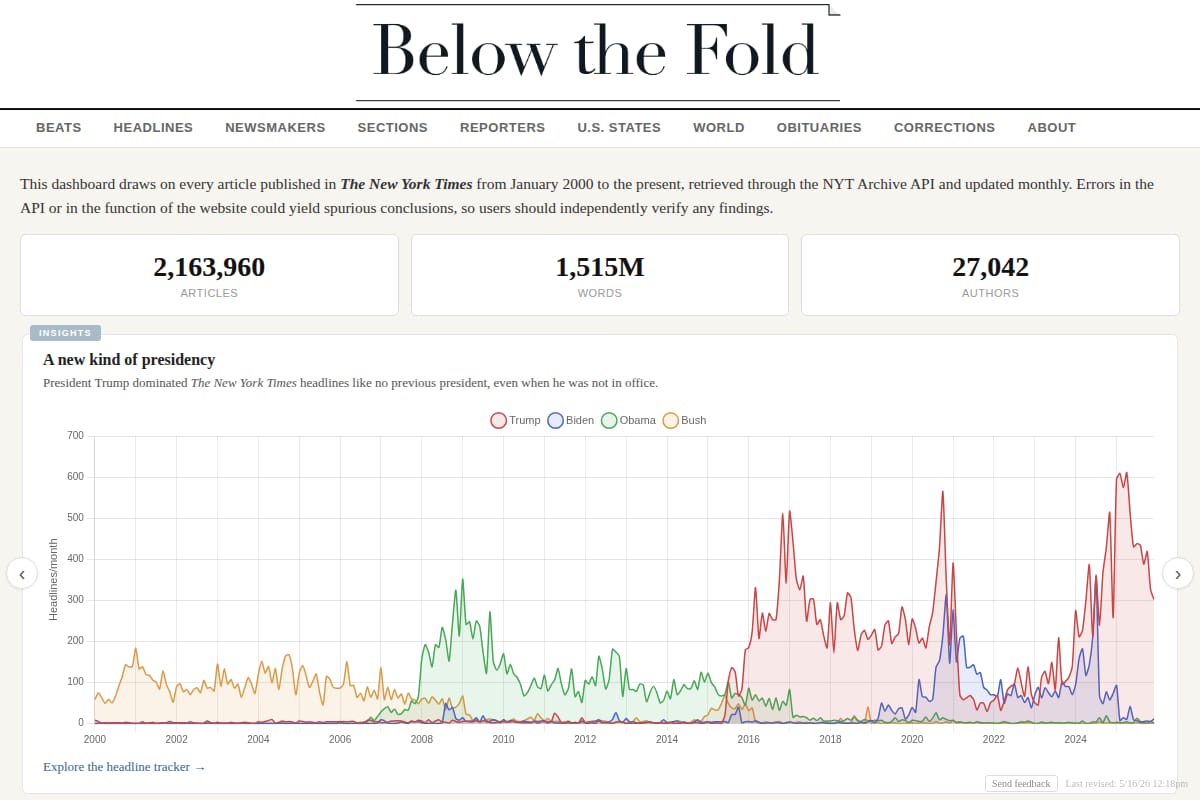
Below the Fold — A New York Times X-Ray Dashboard screenshot

Research / Data Visualization

An interactive dashboard that analyzes New York Times coverage since 2000 using the NYT Archive API, with views for reporters, beats, sections, subjects, geography, obituaries, and corrections.

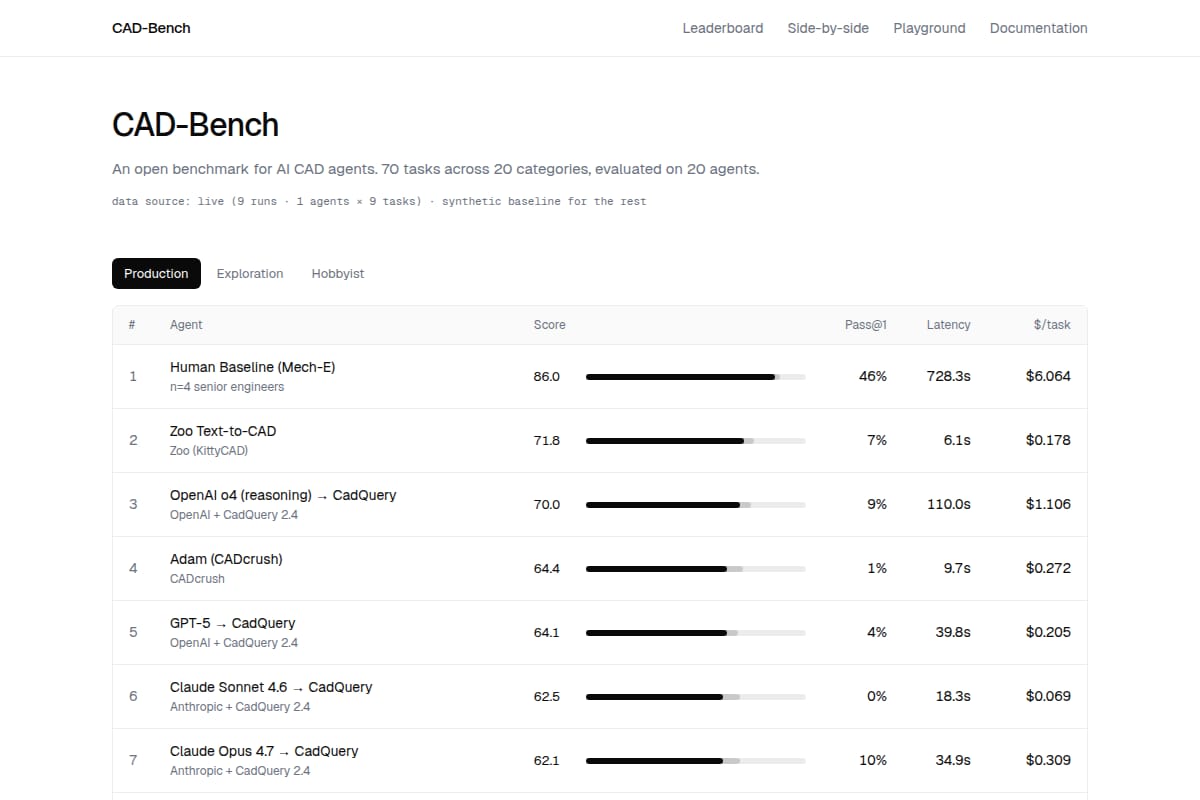
CAD-Bench screenshot
#405 CAD-Bench
88

Research / Knowledge Work

An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition.

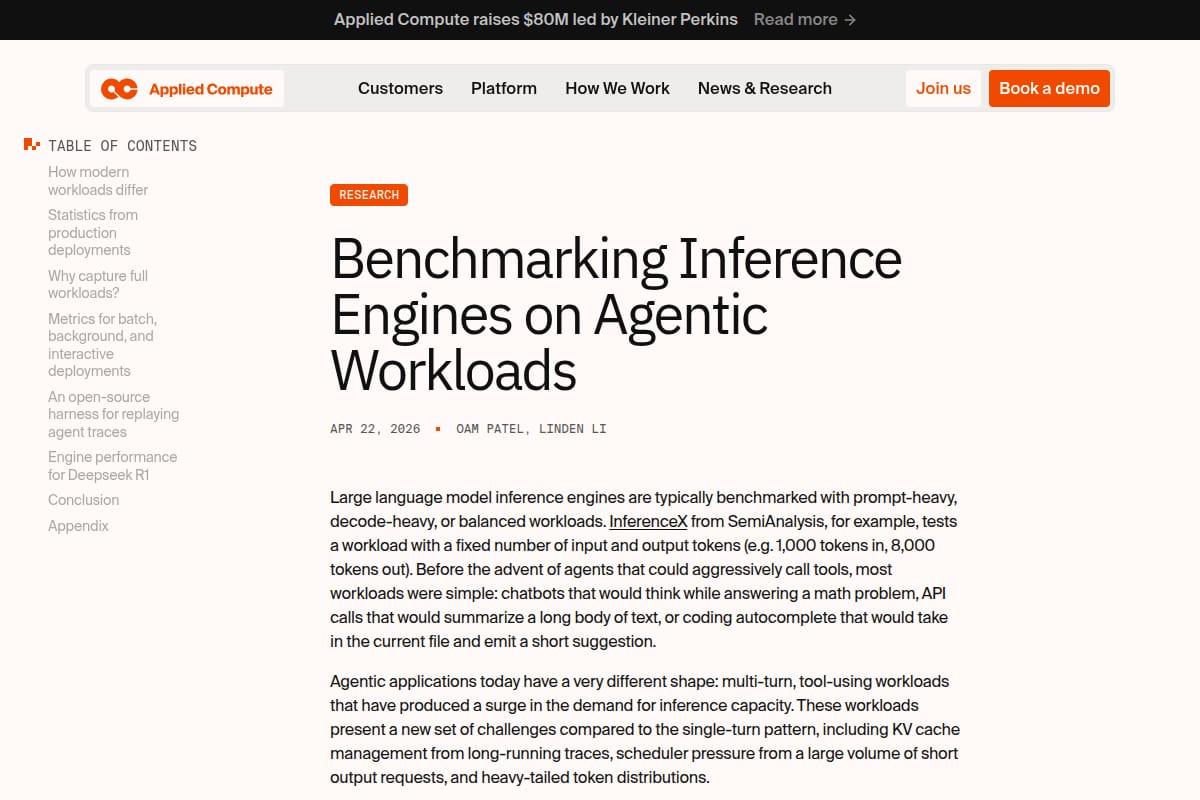
Benchmarking Inference Engines on Agentic Workloads screenshot

Research / Knowledge Work

A research article from Applied Compute on how agentic, tool-using workloads differ from traditional LLM benchmarks, with production observations, workload profiles, and an open-source harness for replaying traces.