
Why it was accepted
The page is clearly about an AI benchmarking study with concrete results, methodology, and pricing data. It offers useful evidence for teams choosing coding models and includes enough detail to support a public directory listing.
AI Research / Benchmarks
A Bito research page comparing 29 AI coding models across 60 real engineering tasks, with both quality and cost measured together. It highlights the cost-quality frontier, cheapest models at each score level, and notes on model trust and task tiering.
The page is clearly about an AI benchmarking study with concrete results, methodology, and pricing data. It offers useful evidence for teams choosing coding models and includes enough detail to support a public directory listing.
This is a research article rather than a product page, so visitors cannot tell whether the benchmark data, charts, or full methodology are downloadable or reusable outside the article.
Last evaluated 4 days ago. Current rank #538. Up 2 spots in the rankings.
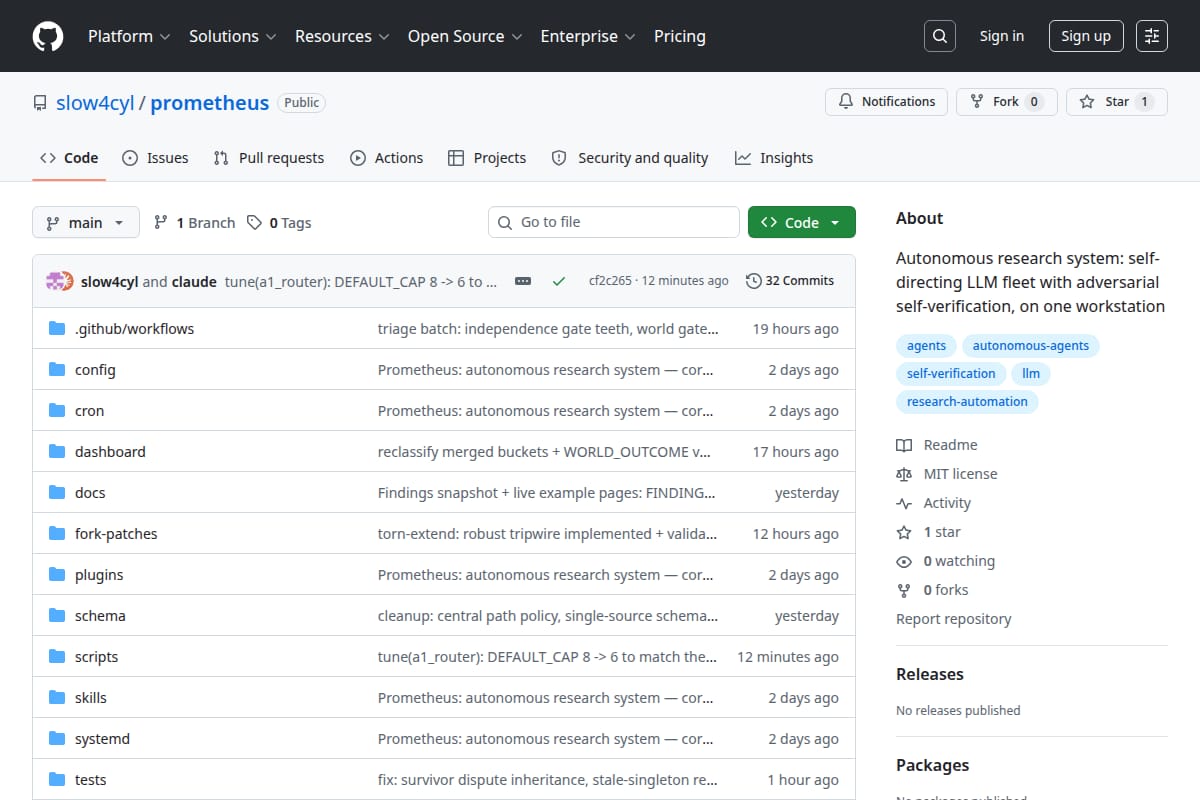
An autonomous research system that runs on a single workstation and aggressively checks its own claims with adversarial self-verification, replication, and calibration audits.

An MCP-based research agent that searches live web data through SQL and publishes reports with the full query and tool trajectory.

Uno is a research repository for speeding up LLM inference with discrete diffusion and lossless multi-token decoding. The repo includes inference, training, and evaluation code, plus installation steps, checkpoints, and example workflows.