
AgentDish directory
KV cache
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
A technical primer that explains how LLM inference works, covering weights in GPU memory, prefill vs. decode, the KV cache, and batching. |
Writing / Copywriting | 84 | ↓ -6 | 53 days ago | Details |
#1424
↓ -3
Proxima
An out-of-tree vLLM plugin that compresses KV cache with STAR-KV to fit more concurrent requests and longer contexts on the same GPU memory budget. |
Developer Tool / LLM Serving / vLLM | 83 | ↓ -3 | 65 days ago | Details |

A research repo that replays real Claude Code and Mooncake traces to test prefix-cache eviction policies and compare them against LRU. |
Developer Tools / Code Assistant | 82 | ↓ -2 | 36 days ago | Details |
#1826
↑ +2
PSI KV Governor
Reference implementation for using Linux Pressure Stall Information to trim an LLM KV cache under memory pressure. The repo includes requirements, basic usage commands, a simulator, a llama.cpp runner, and benchmark scripts with example results. |
Developer Tools / AI Infrastructure | 81 | ↑ +2 | 110 days ago | Details |
#1851
↓ -1
Galahad
Galahad is an AI memory layer that saves and restores model KV cache, supports document recall, and plugs into vLLM, SGLang, and llama.cpp. The page also shows agent features like replay, branching, rewind, and fault-finding. |
Developer Tools / AI Infrastructure | 80 | ↓ -1 | 5 days ago | Details |

#2100
↑ +6
EdgeSync-LLM
A GitHub repository for an engine-agnostic KV cache fragment system for on-device LLM inference, with Android and Go components, adapters for llama.cpp/MLC-LLM/ONNX Runtime, and benchmark and monitoring code. |
Developer Tools / AI/LLM Inference | 78 | ↑ +6 | 108 days ago | Details |

arXiv paper on a cache-merging method for multi-agent latent reasoning, framing KV-cache composition as a convergent replicated state with deterministic merging. |
Research / AI Research Paper | 74 | ↓ -1 | 105 days ago | Details |
#2433
→ 0
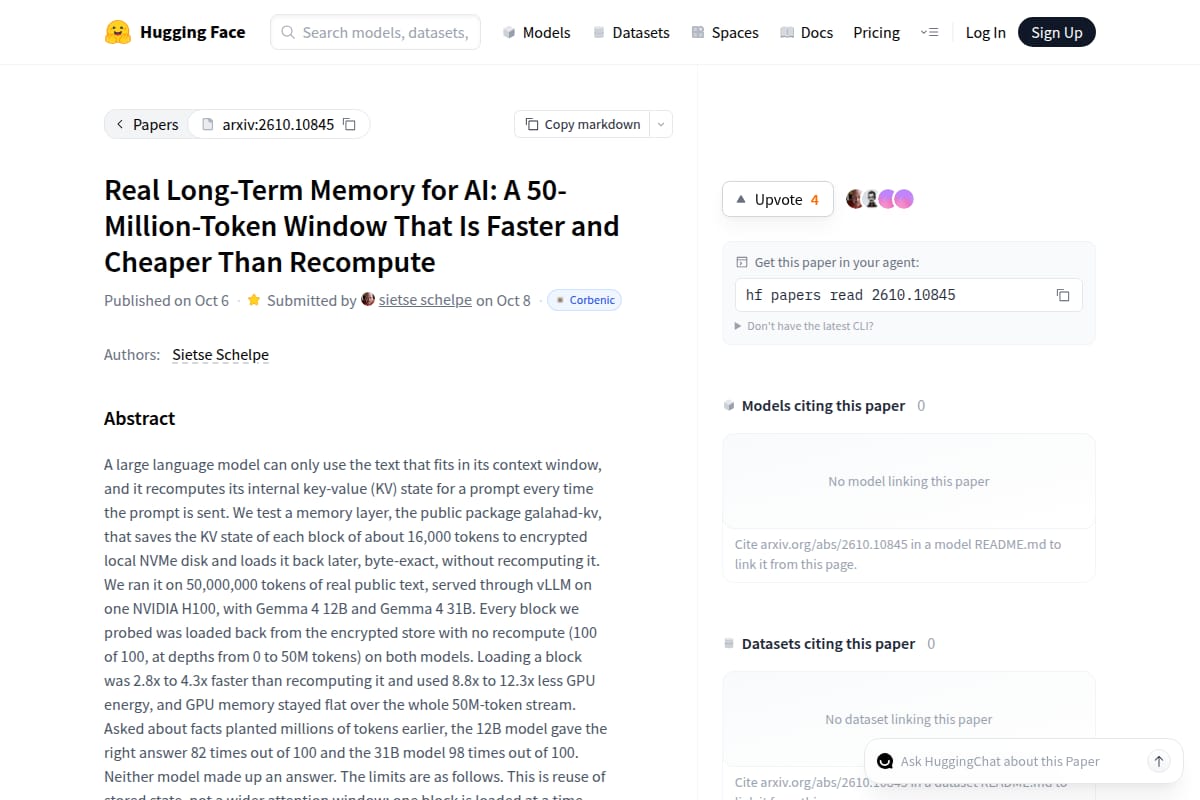
Real Long-Term Memory for AI: A 50-Million-Token Window That Is Faster and Cheaper Than Recompute
A Hugging Face paper page describing a memory layer for LLMs that stores KV state to encrypted NVMe and reloads it later without recomputing, with results from 50M-token experiments on Gemma models. |
Research / AI Memory / Long-Context | 71 | → 0 | 7 days ago | Details |