Research / AI Benchmarks & Experiments

OpenAI uses substantially different model for subs vs. API?

A reproducible GitHub research repo comparing Codex reasoning-token usage between API and ChatGPT Pro access across 960 completed responses, with code, data, and verification steps included.

Clear24/30
Useful24/30
Specific17/20
Complete17/20
OpenAI uses substantially different model for subs vs. API? screenshot

Why it was accepted

The page clearly presents an AI-related research project with a concrete question, visible experimental results, and reproducible code and analysis steps. It is useful for AI builders or researchers who want to inspect or replicate the comparison between API and subscription access.
Weakness

It’s a narrow experiment rather than a general-purpose tool, and the crawl does not show how broadly the findings apply beyond the two prompts and model/level combinations tested. The page also doesn’t surface a quick standalone dashboard or summary artifact outside the repository.

Review status

9 days ago #1546 ↓ -2

Last evaluated 9 days ago. Current rank #1546. Down 2 spots in the rankings.

Score history

82

Related listings

Primus AI Researcher – Free screenshot

Research / Knowledge Work

Primus is an autonomous AI researcher that hypothesizes, reads papers, writes code, runs experiments on compute, and drafts research papers. The page shows example tasks, published-paper claims, waitlist access, and positioning for ML research workflows.

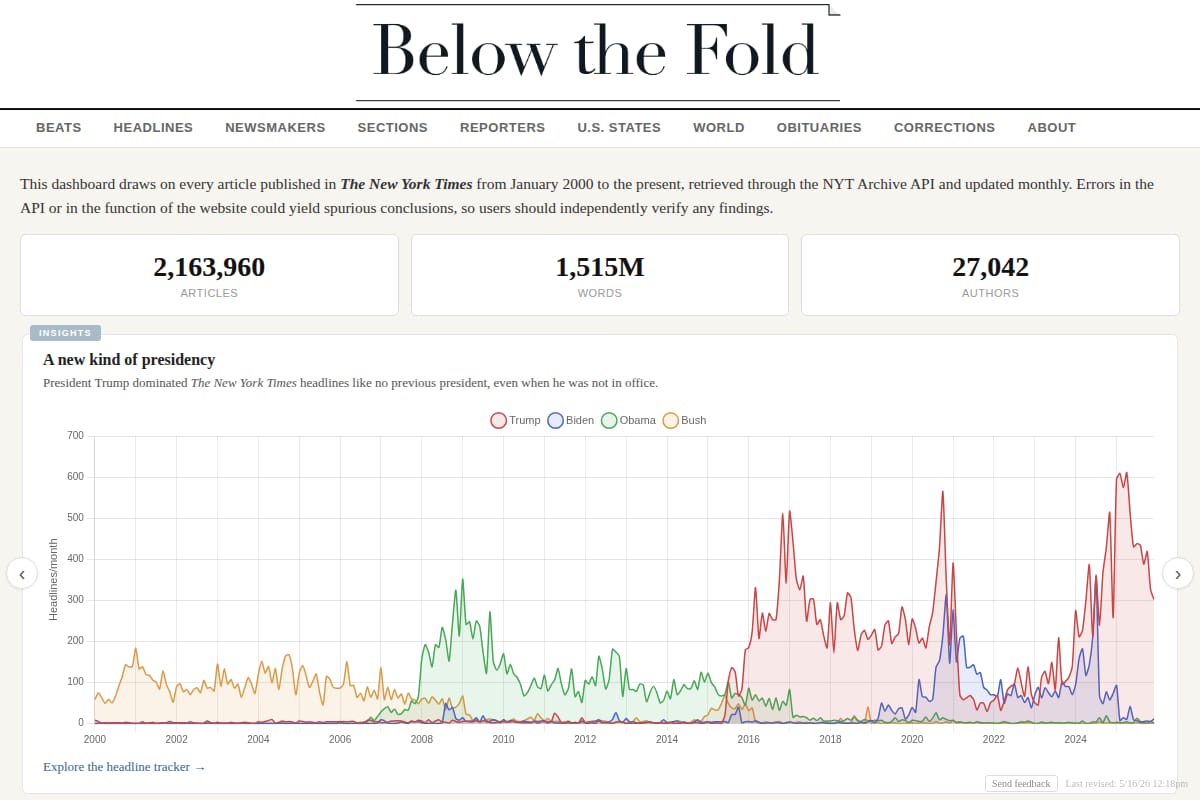
Below the Fold — A New York Times X-Ray Dashboard screenshot

Research / Data Visualization

An interactive dashboard that analyzes New York Times coverage since 2000 using the NYT Archive API, with views for reporters, beats, sections, subjects, geography, obituaries, and corrections.

CAD-Bench screenshot
#405 CAD-Bench
88

Research / Knowledge Work

An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition.

Benchmarking Inference Engines on Agentic Workloads screenshot

Research / Knowledge Work

A research article from Applied Compute on how agentic, tool-using workloads differ from traditional LLM benchmarks, with production observations, workload profiles, and an open-source harness for replaying traces.