
AgentDish directory
AI Research AI Tools
Accepted listings in this category.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
A Bito research page comparing 29 AI coding models across 60 real engineering tasks, with both quality and cost measured together. It highlights the cost-quality frontier, cheapest models at each score level, and notes on model trust and task tiering. |
AI Research / Benchmarks | 86 | ↑ +2 | 16 days ago | Details |
#722
↑ +2
Prometheus
An autonomous research system that runs on a single workstation and aggressively checks its own claims with adversarial self-verification, replication, and calibration audits. |
AI Research / Autonomous Research Systems | 86 | ↑ +2 | 97 days ago | Details |

#1074
↓ -6
Keenable SELECT
An MCP-based research agent that searches live web data through SQL and publishes reports with the full query and tool trajectory. |
AI Research / Web Search / Data Extraction | 84 | ↓ -6 | 43 days ago | Details |

#1395
↓ -3
Uno
Uno is a research repository for speeding up LLM inference with discrete diffusion and lossless multi-token decoding. The repo includes inference, training, and evaluation code, plus installation steps, checkpoints, and example workflows. |
AI Research / LLM Efficiency / Inference | 83 | ↓ -3 | 41 days ago | Details |

An arXiv paper describing an open library of 163 procedural skills for research agents across 16 scientific areas, with versioned instruction files and accompanying reference material or runnable scripts. |
AI Research / Research Agents | 82 | ↓ -2 | 42 days ago | Details |
#1709
↓ -2
Socrates
Open-source multi-agent protocol for AI research agents. It pairs a tool-using Scientist with a question-only advisor that can only ask questions and approve plans, and the README includes quick-start setup plus notes on reproducing results on MLE-bench/Kaggle tasks. |
AI Research / Multi-agent systems | 82 | ↓ -2 | 112 days ago | Details |
A research post from Telem AI measuring cold-start latency across nine web-search APIs, with cache behavior, tail latency, and agent-query comparisons. |
AI Research / Benchmarking / Latency Research | 81 | ↑ +2 | 53 days ago | Details |
#1832
↑ +2
EuroMesh
A sourced model and short report exploring whether Europe could train a sovereign frontier AI model using public compute it already owns, with reproducible code, datasets, and a PDF report. |
AI Research / Analysis / Reports | 81 | ↑ +2 | 122 days ago | Details |
#1849
↓ -73
MarCognity-AI
An open-source research framework for structured LLM evaluation, claim verification, and source-grounded reflective reasoning. The repo describes modular components for retrieval, semantic scoring, skeptical claim checking, and benchmark-style epistemic assessment. |
AI Research / Evaluation / Verification Framework | 81 | ↓ -73 | 163 days ago | Details |
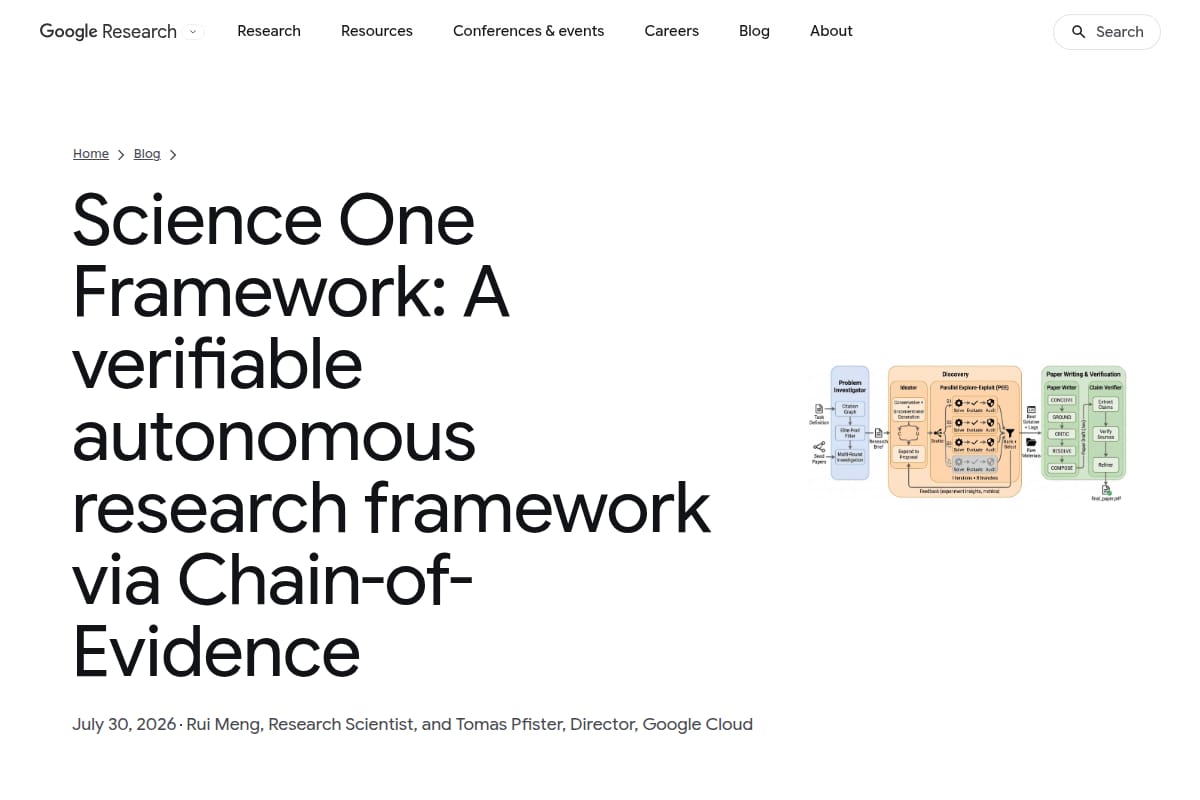
Google Research article describing Science One Framework, an autonomous research prototype focused on verifiable AI-generated research through evidence chains and claim verification. |
AI Research / Autonomous Research | 80 | ↓ -1 | 67 days ago | Details |
#1942
↑ +2
Unslopping AI
Meta AI research on RL-XAR, a method for training language models toward expert-level writing using expert-aligned rubrics and reinforcement learning. The page explains the problem, the rubric-learning loop, and experiments on paper sections, story writing, and Wikipedia-style text. |
AI Research / Writing Evaluation / RLHF | 79 | ↑ +2 | 17 days ago | Details |
#1972
↑ +2
Two Eyes Arguing
An interactive AI experiment where two photorealistic eyes argue about everyday moral scenarios, grounded in the sociology of justification and symbolic boundaries. |
AI Research / Interactive Demo | 79 | ↑ +2 | 76 days ago | Details |
#2038
↑ +6
PICARD: Parsing Incrementally for Constrained Auto-Regressive Decoding from Language Models
arXiv paper on constraining LLM decoding with incremental parsing to reduce invalid SQL and improve text-to-SQL results. |
AI Research / LLM Decoding / Text-to-SQL | 78 | ↑ +6 | 22 days ago | Details |
#2044
↑ +6
Berge–Fulkerson conjecture · Prove Together
A Prove Together problem page for the Berge–Fulkerson conjecture, with a formal Lean target, provenance notes, reusable lemmas, and discussion around agent-assisted proof work. |
AI Research / Formal theorem proving | 78 | ↑ +6 | 32 days ago | Details |

#2047
↑ +6
Training a 3.8B LLM to 0.384 CORE for $998
A detailed technical write-up about training a 3.8B-parameter language model from scratch, including setup, throughput improvements, ablations, benchmarks, and cost/performance results. |
AI Research / LLM Training / Write-up | 78 | ↑ +6 | 35 days ago | Details |
#2113
↑ +6
MiroThinker
MiroThinker is a science-focused AI research app that emphasizes prediction, verification, and evidence-backed answers. The page also points to a MiroMind app and suggests use cases across finance, medicine, and regulation. |
AI Research / Deep Research Agent | 78 | ↑ +6 | 125 days ago | Details |
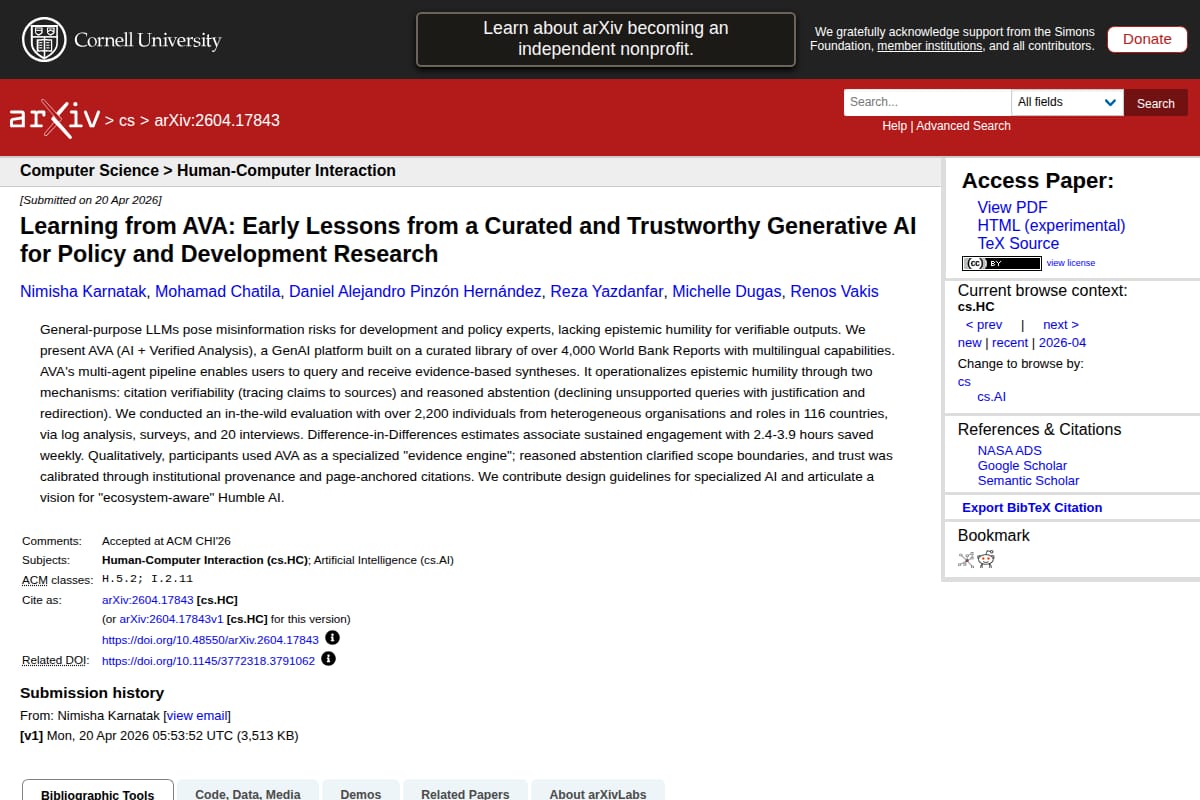
arXiv paper describing AVA, a GenAI platform for policy and development research built on 4,000+ World Bank reports. The abstract highlights multilingual support, evidence-based synthesis, citation verifiability, and reasoned abstention when queries cannot be supported. |
AI Research / Trustworthy Generative AI | 78 | ↑ +6 | 140 days ago | Details |
#2137
↑ +6
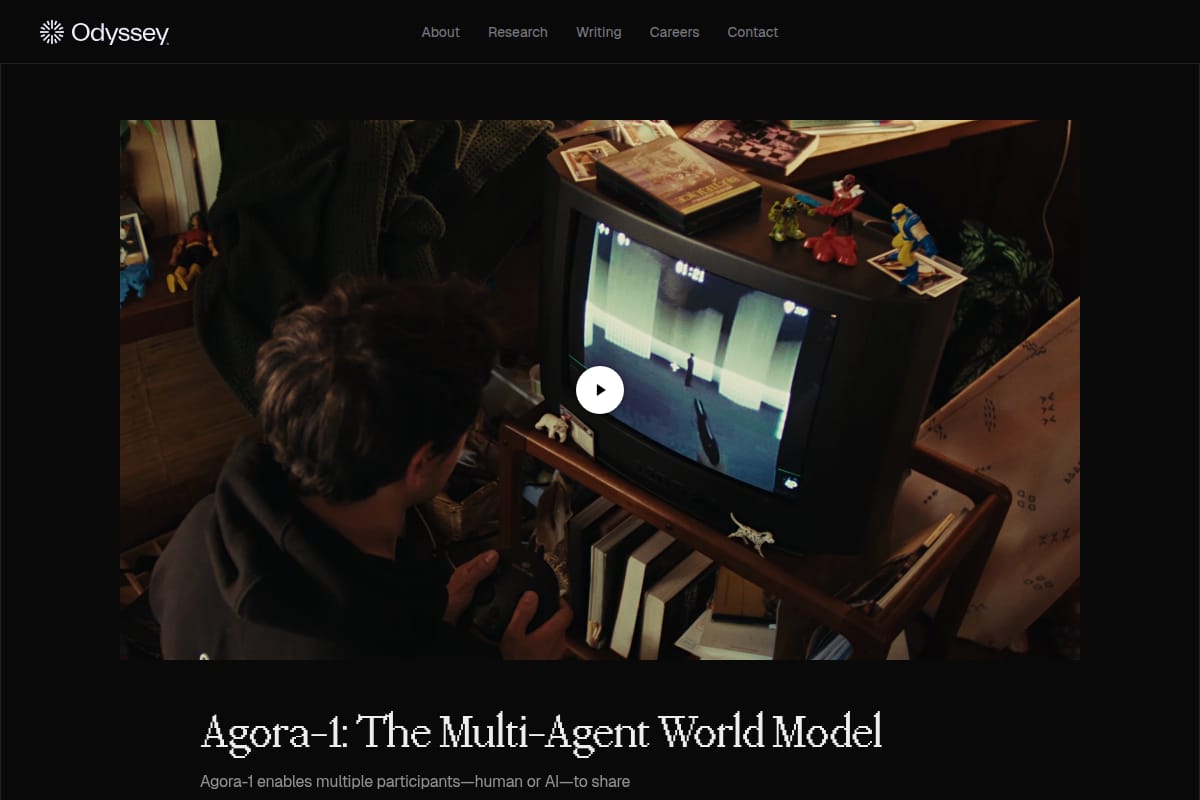
Agora-1: The Multi-Agent World Model
Agora-1 is a multi-agent world model from Odyssey that simulates shared real-time environments for up to four participants, human or AI, with a focus on gaming, robotics, reinforcement learning, and foundation model research. |
AI Research / World Models | 78 | ↑ +6 | 149 days ago | Details |
Apple Machine Learning Research paper proposing LaDiR, a reasoning framework that combines a VAE-based latent space with latent diffusion to improve LLM text reasoning and iterative refinement. |
AI Research / LLM Reasoning | 78 | ↑ +5 | 162 days ago | Details |

#2175
→ 0
Maith
Maith is an open-source research workspace for exploring open mathematics with AI while keeping proof standards explicit and checkable. |
AI Research / Mathematics | 77 | → 0 | 86 days ago | Details |
#2264
↓ -1
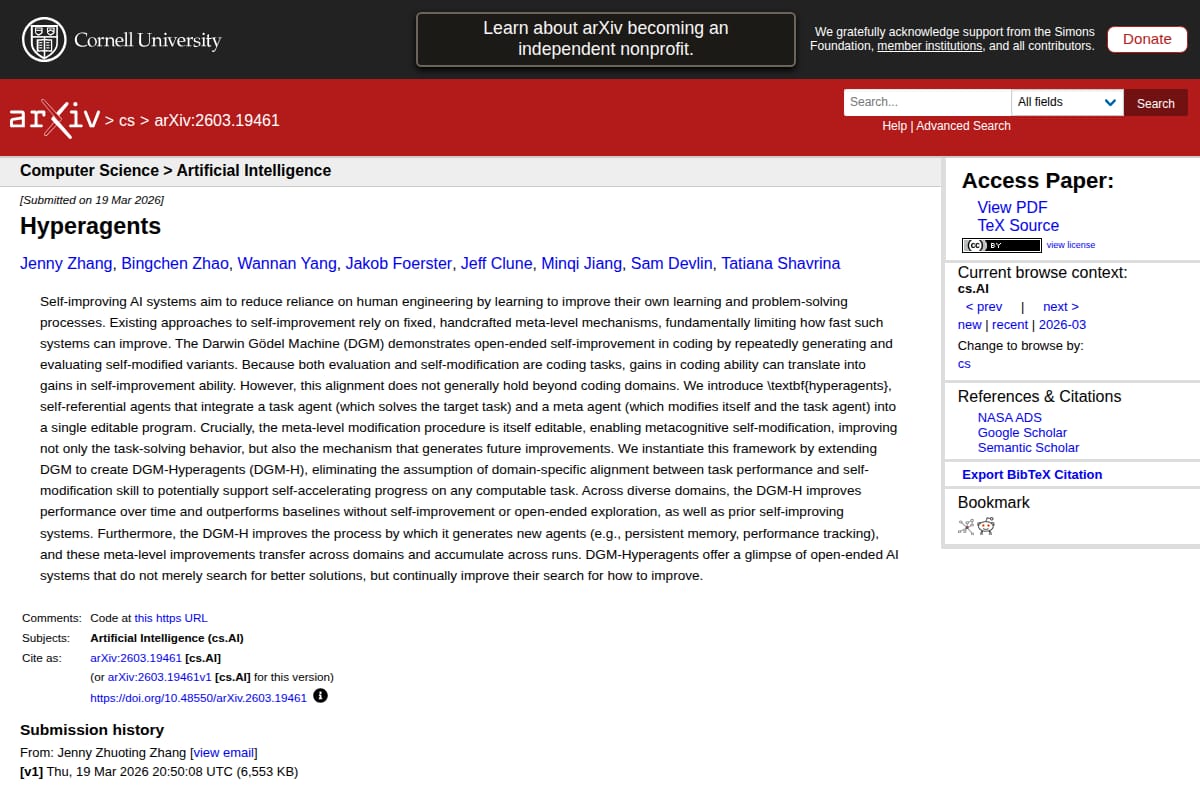
Hyperagents
Research paper introducing hyperagents, a self-referential agent framework that combines a task agent and a meta agent into one editable program. The abstract describes a DGM-based system that improves both task performance and its own improvement process across domains. |
AI Research / Self-Improving Agents | 76 | ↓ -1 | 145 days ago | Details |
A GitHub research project documenting a long-form, multi-model analysis of LLM behavior across Claude, Gemini, ChatGPT, and Grok. The repo includes an executive summary, screenplay, technical white paper, and archive of logs and chat records. |
AI Research / LLM Evaluation & Analysis | 75 | → 0 | 142 days ago | Details |
#2295
↓ -1
SuperLocalMemory 4.0
An arXiv paper describing a governed, local-first memory system for AI agents, with audit trails, role-based access, verified erasure, and fault-injection results. The page also links to associated code and a Zenodo DOI. |
AI Research / Memory Systems | 74 | ↓ -1 | 11 days ago | Details |
#2309
↓ -1
Extrapolation Under an Exact Verifier
A research page describing a verified circle-packing result produced by a frozen language model with an external memory loop, with published trace, attempts archive, and repository code/data. |
AI Research / LLM Experiments | 74 | ↓ -1 | 45 days ago | Details |